When Models Learn
Test-time training allows AI models to update weights during inference, trading increased compute for improved personalization and constant-time memory usage.
Deep dive
- Memory efficiency: TTT replaces the linear KV-cache growth with fixed-size model weights, keeping memory footprint constant during long sessions.
- Performance: Research suggests TTT can be up to 2.7x faster in terms of inference latency.
- Deployment cost: Service providers must host separate model checkpoints per user, significantly increasing compute requirements compared to static, shared models.
- Use case differentiation: Static, frozen models remain more efficient for one-off tasks like basic customer support, while TTT is better suited for persistent, state-heavy tasks like coding assistants.
Decoder
- Test-time training (TTT): An inference technique where a model takes a gradient step on the input prompt to adjust its weights, allowing the model to 'learn' from the context dynamically.
- KV-cache: A memory structure in Transformer models that stores key and value representations of previous tokens to speed up text generation. Growth is proportional to context length.
Original article
In short: Explains test-time training through the analogy of a GPS learning a persistent shortcut around daily traffic rather than a one-time reroute: the model takes a gradient step on the prompt it's answering, so its weights change as it works. Traces three implications, flat memory instead of a linearly growing KV-cache, the provider cost of serving a separate model per user, & faster inference, then states the tension as a tradeoff between serving long context and serving many people, & grounds it in concrete use cases, a coding agent that earns back its per-user cost over a long session versus a one-off query a shared frozen model handles just as well.
Every model you’ve ever used froze the day its training ended. The answers are the same even if you have used it every day.
What if a model kept learning as you use it?
A GPS learns a persistent shortcut around daily traffic on northbound Highway 101, not just a one-time reroute. Test-time training does that to a model as it works. As you use the AI, the model changes its weights, changes how it thinks about its memories, to answer you better.
The changes are more profound than finding an off-ramp to an access road past a highway junction chokepoint.
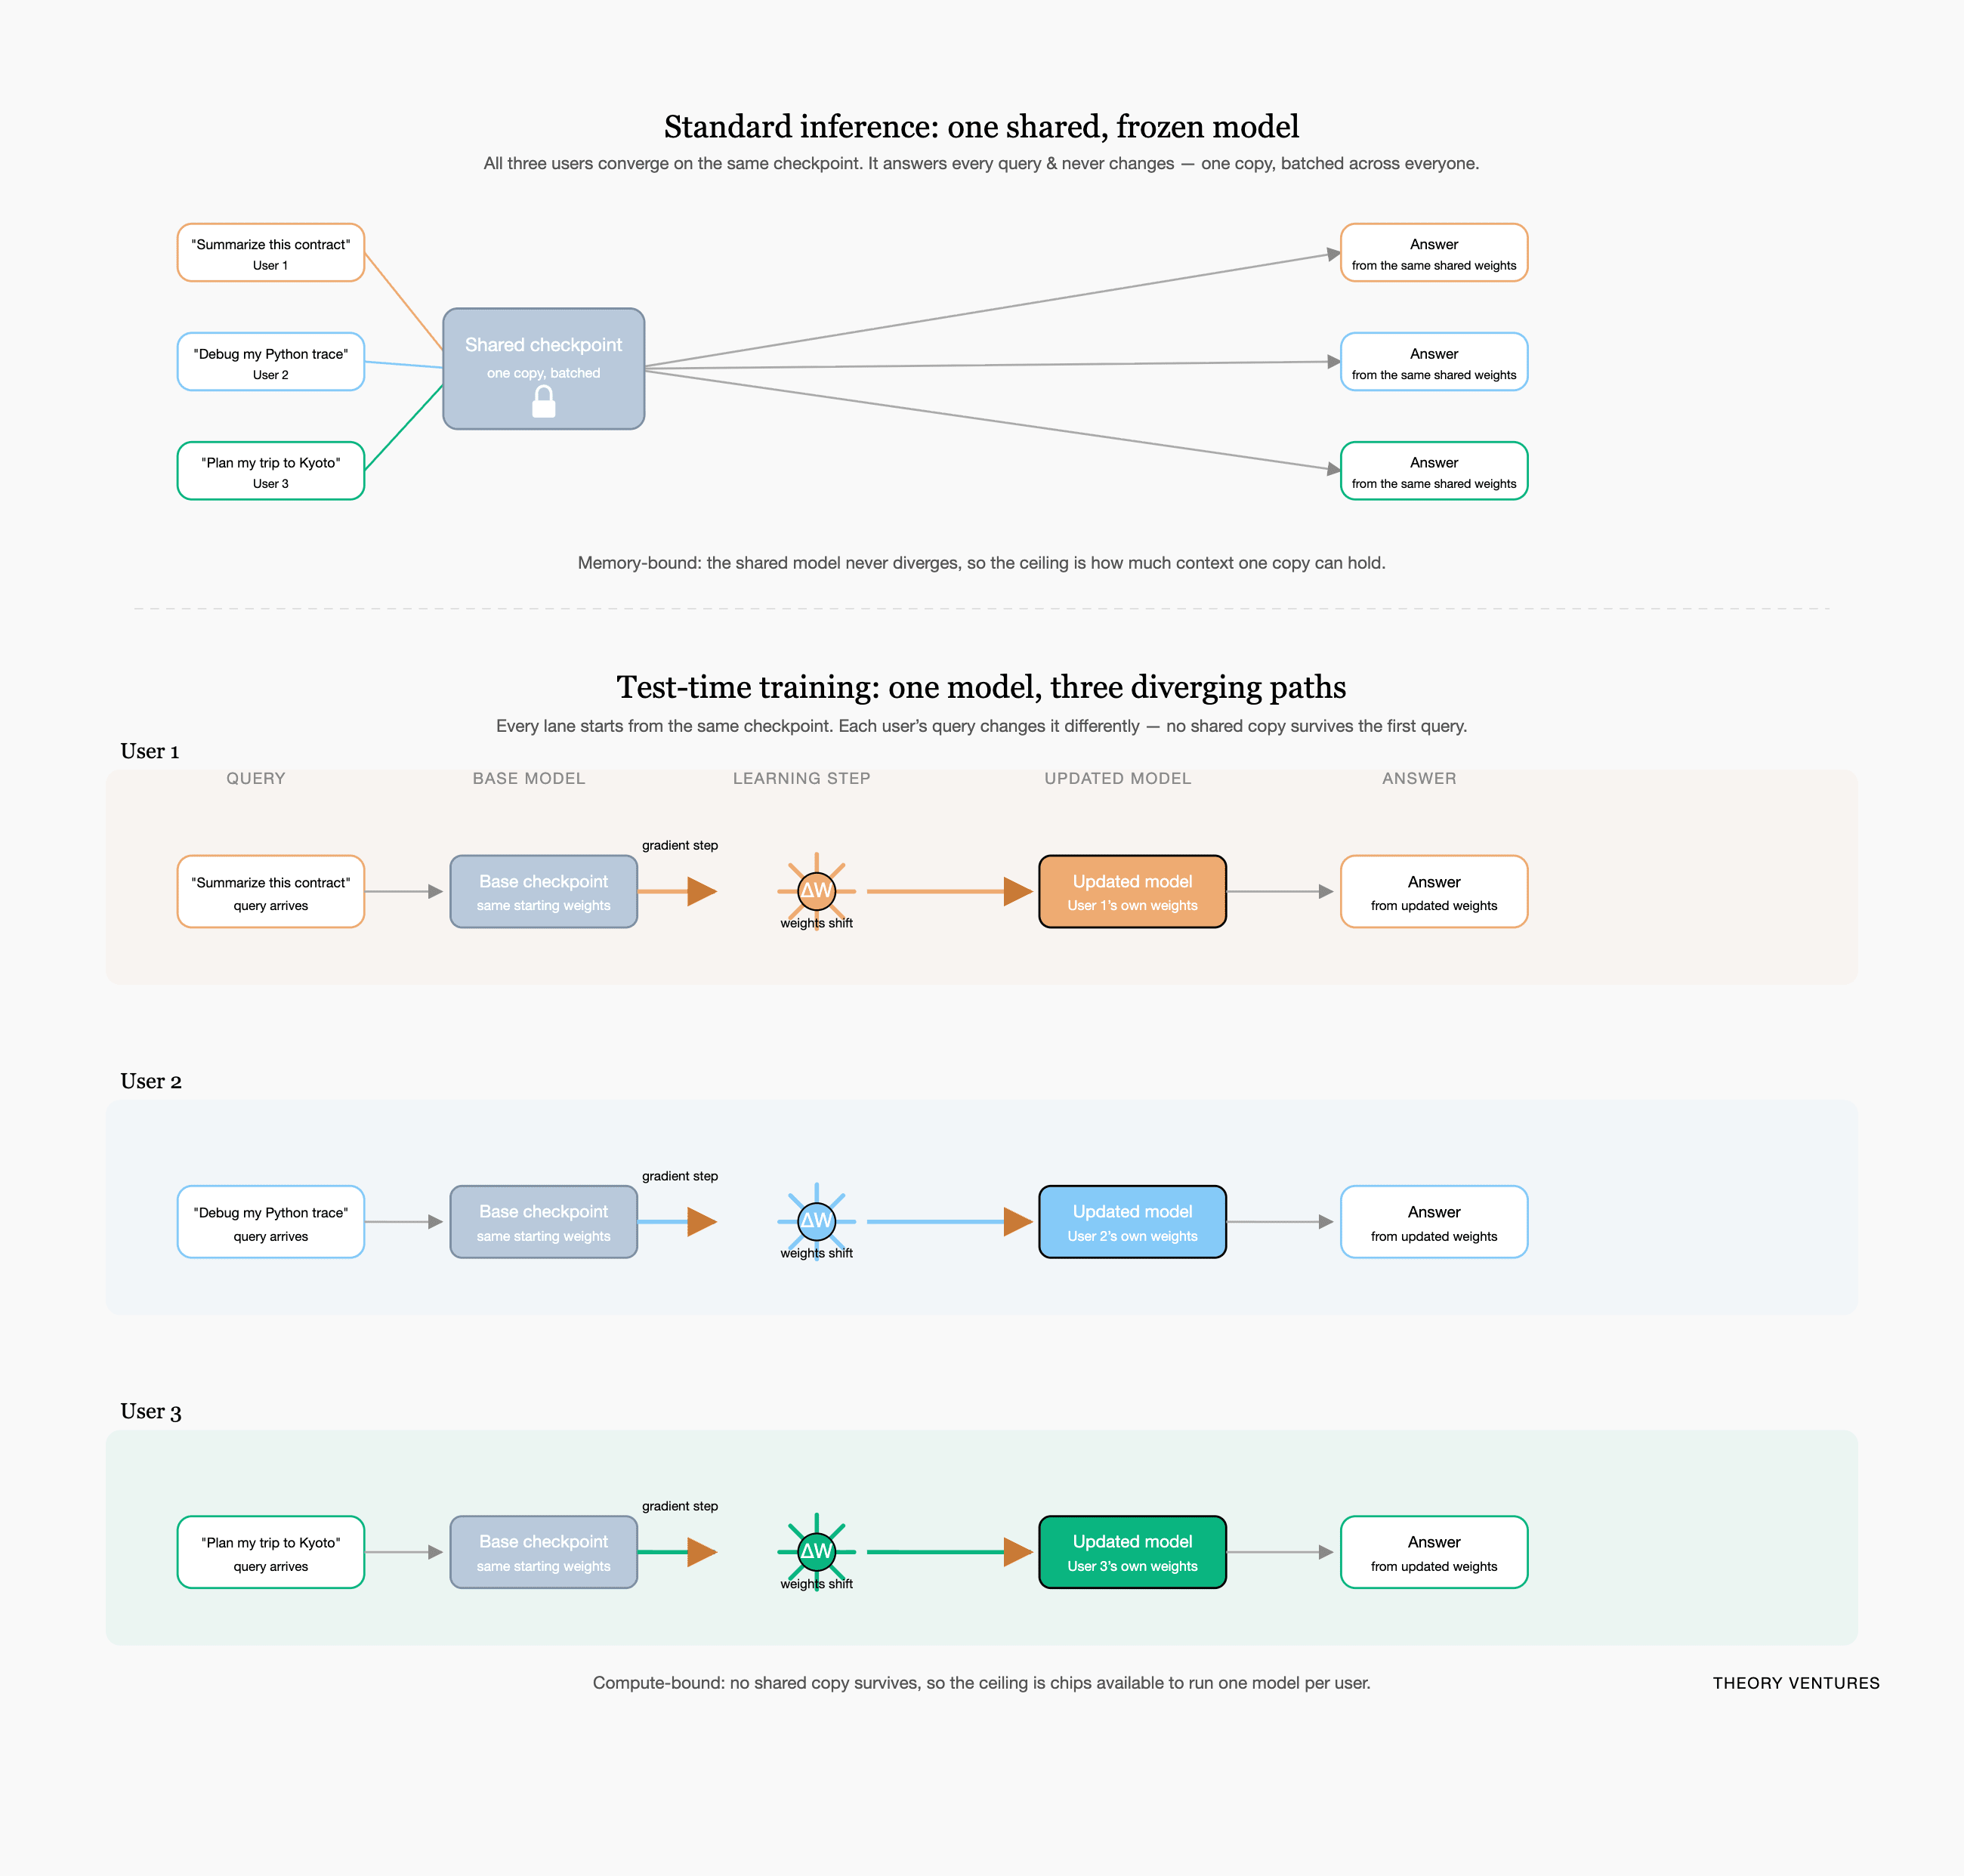
Memory requirements plummet. A standard transformer keeps a KV-cache, a running record of every earlier token, so its memory grows linearly with context, every additional token adds to the running record. Test-time training folds that history into a fixed-size set of weights instead of a growing cache, so memory stays flat no matter how long the conversation runs.
The model provider now has to serve a separate model to each person. Once a model updates on your prompt, it is no longer the model that answered your neighbor’s, so a single checkpoint serving millions of users becomes millions of slightly different models, each shaped by the person using it. That divergence is the provider’s problem to solve: a GPU provider needs a copy in flight per user instead of one shared copy for everyone, which means more compute, more chips, to serve the same number of people.
It’s much faster. Stanford research on small models indicates it can be up to 2.7 times faster, because a test-time trained model’s inference latency stays constant no matter how long the context runs, the way a standard transformer’s does not. In-Place TTT also ships drop-in, lifting a 4b model to competitive 128k-context performance with no retraining.
Here is the tension. Standard AI is limited by memory, test-time AI is limited by compute & chips, so a provider picks based on whether it’s serving long context or serving many people.
That cost is only worth paying where personalization earns its keep. A coding agent that learns your codebase’s conventions, the resilient persistent bugs, ultimately should provide some form of lock-in via memory, so the per-user cost pays for itself. A one-off customer support question doesn’t need any of that. A shared, frozen, potentially fine-tuned model answers it just as well & costs the provider far less to serve.
Test-time training will be a key part of the discourse throughout the end of 2026 & beyond. It has the potential to change the current economics of AI.
Fresh dev news, AI-digested daily. Never miss a trend at devoured.fyi