DEVOURED
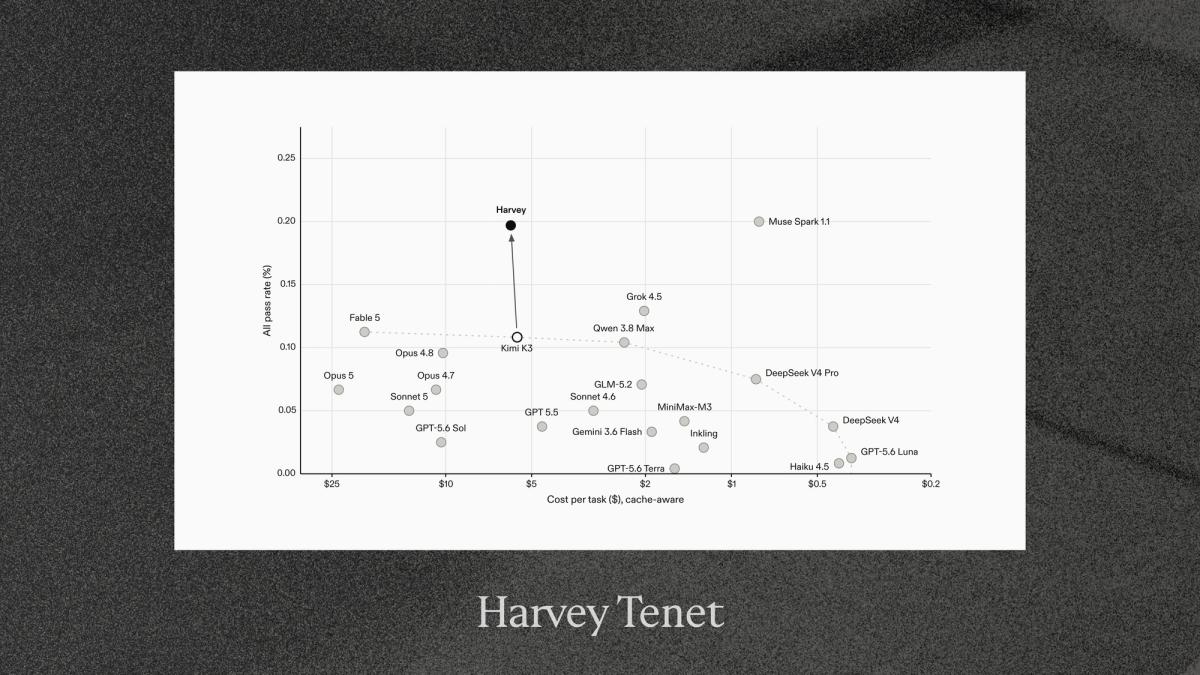
Harvey post-trains Kimi K3 for long-horizon legal work
Harvey has post-trained a Kimi K3 model specifically for long-horizon legal tasks using asynchronous reinforcement learning.
What: Harvey Tenet, the resulting model, uses 'Recursive Language Models' to handle large-scale document context and includes specialized tools for M&A diligence and review tables. The model showed significant improvements in task completion on legal benchmarks while reducing token usage.
Why it matters: This highlights a trend toward 'workflow-aware' models where the model is not just trained on raw text, but specifically tuned for the constraints, citations, and structure of a specific professional service domain.
Deep dive
- Uses asynchronous reinforcement learning (RL) with group-sequence policy optimization (GSPO).
- Trained in sandboxed workspaces on 1,750 legal task environments.
- Achieves 'state-of-the-art' performance on LAB Contracts benchmark.
- Incorporates memory and emergent taxonomies for law firm knowledge search.
- Reduces token usage for complex tasks by up to 58% through more efficient, targeted reasoning.
- Employs specialized tools for structured data extraction and citation management.
Decoder
- GSPO (Group-Sequence Policy Optimization): A reinforcement learning optimization algorithm where advantages are calculated over groups of independent rollouts.
- Recursive Language Models (RLM): A system architecture where a root agent orchestrates sub-agents to process and synthesize document-heavy tasks.
Original article
Full article content is not available for inline reading.
Explore all 58 articles in today's digest
Fresh dev news, AI-digested daily. Never miss a trend at devoured.fyi