How OpenAI Delivers Low-Latency Voice AI for 900M Users
OpenAI scaled its real-time voice infrastructure by splitting WebRTC into a stateless packet relay and a stateful transceiver to overcome Kubernetes limitations.
Deep dive
- Kubernetes/WebRTC Conflict: Standard WebRTC setups require stable IP/port mappings, clashing with the dynamic, disposable nature of Kubernetes pods.
- The Split Architecture: OpenAI separates the stack into a stateless relay (routing) and a stateful transceiver (handling ICE/DTLS/SRTP).
- Routing via ICE ufrag: To avoid external database lookups on the hot path, OpenAI embeds routing hints into the ICE ufrag field during initial signaling, enabling the relay to direct the first packet to the correct transceiver.
- Performance Optimizations: Used Go's userspace networking, SO_REUSEPORT for kernel-level load balancing, and runtime.LockOSThread to maintain CPU cache locality.
- Avoidance of Kernel Bypass: The team opted for optimized Go code over complex kernel-bypass frameworks, finding it sufficient for their latency requirements.
- Redis Integration: A Redis cache stores established mappings to allow for fast state recovery if a relay pod restarts.
Decoder
- WebRTC: An open-source protocol enabling real-time audio/video communication directly between browsers or applications.
- ICE (Interactive Connectivity Establishment): A framework for finding the best path for two devices to connect through firewalls and NATs.
- ufrag (Username Fragment): A component of ICE credentials exchanged during session setup, repurposed here as a routing key.
- SFU (Selective Forwarding Unit): A server architecture that receives a media stream from one participant and selectively forwards it to others; commonly used in video conferencing like Zoom.
- STUN (Session Traversal Utilities for NAT): A protocol used to discover public IP addresses and NAT behavior.
- SRTP (Secure Real-time Transport Protocol): Provides encryption, message authentication, and integrity for voice and video traffic.
- SO_REUSEPORT: A Linux socket option that allows multiple processes or threads to bind to the same port, improving load distribution.
Original article
How OpenAI Delivers Low-Latency Voice AI for 900M Users
OpenAI runs voice AI for 900 million users a week, and they use WebRTC for it because the alternative would mean reinventing how the internet handles live audio.
The catch is that WebRTC was designed for servers with stable IPs and ports, and Kubernetes treats those addresses as disposable. The conventional answer at this scale is an SFU, which suits multiparty workloads like group video calls, but OpenAI’s traffic is overwhelmingly one user talking to one model.
To deal with this, their architecture splits the stack into two pieces:
- A stateless relay handles protocol-aware packet routing at the geographic edge.
- A stateful transceiver owns all the heavy WebRTC state.
The trick that ties them together is using the ICE ufrag, a field the protocol already exchanges during setup, as a routing key that the relay can read off the first packet of a new session. Everything else, from Global Relay to the userspace Go implementation to the Redis cache and the careful socket-level optimizations, builds on top of that core idea.
Why Latency Matters For Voice AI
Voice AI either feels like a conversation or it feels like a walkie-talkie. The line between those experiences is measured in milliseconds.
When the network pauses between hearing a user and responding, the illusion breaks. Pauses turn awkward, interruptions get clipped, and users are compelled to cut off the AI mid-sentence, which is also kind of rude. In other words, voice AI only feels natural if the conversation moves at the speed of speech.
The harder constraint underneath is the continuous-stream property. Audio has to arrive at the model as a steady flow, rather than as a single upload after the user finishes talking. That stream is what lets the model start transcribing, reasoning, and calling tools while the user is still speaking. The experience collapses into push-to-talk once it breaks.
For OpenAI specifically, those constraints translate into three concrete requirements:
- The system has to reach 900 million weekly active users wherever they are.
- Connection setup has to be completed quickly enough that users can start speaking as soon as a session begins.
- Round-trip time for audio has to stay low and stable so turn-taking feels crisp.
WebRTC is the protocol the industry built for this kind of work. It is a bundle of smaller protocols (ICE for figuring out how two endpoints reach each other across firewalls, DTLS for encrypting the channel, SRTP for the audio packets, and RTCP for quality feedback).
The Original Architecture
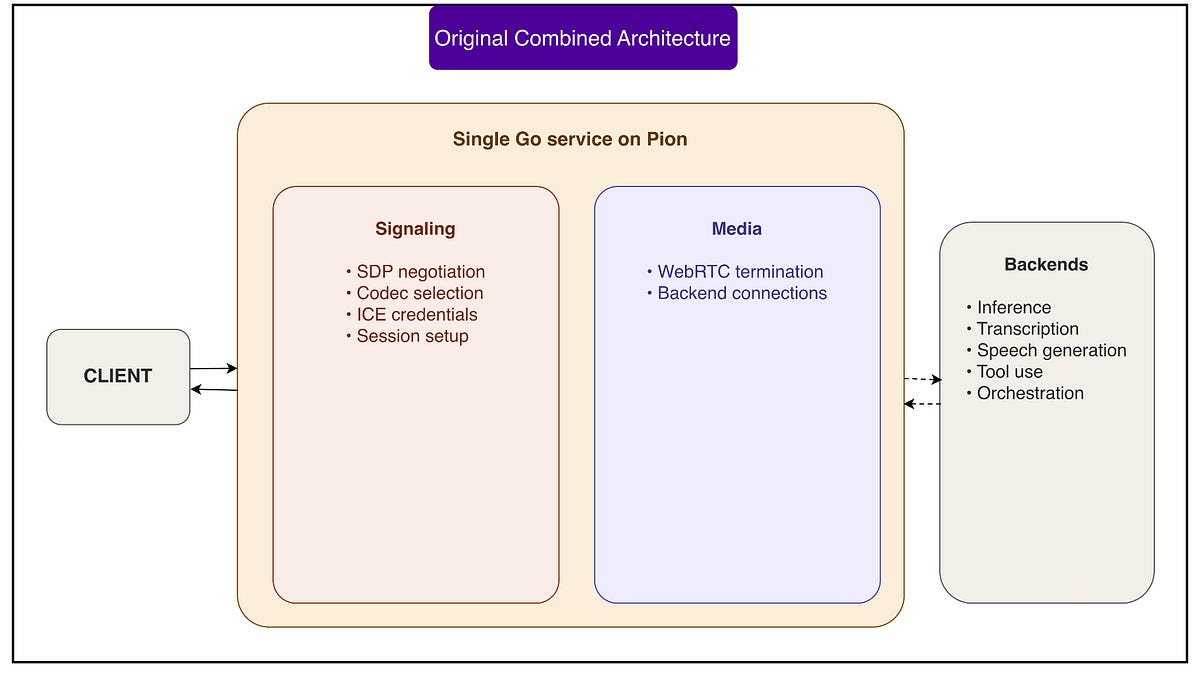
The first version of OpenAI’s WebRTC infrastructure was a single Go service built on Pion. It handled both jobs in one place:
- On the signaling side, the service negotiated SDP (the format clients and servers use to describe a session), selected codecs, generated ICE credentials, and set up sessions.
- On the media side, the service terminated WebRTC connections from clients and maintained upstream connections to the backend services that run the AI models, including inference, transcription, speech generation, tool use, and orchestration.
That combined service still powers ChatGPT voice, the Realtime API’s WebRTC endpoint, and several research projects, and it has handled that work well. The question OpenAI ran into was how to deploy it on Kubernetes, the container orchestration system that runs most modern cloud infrastructure.
Kubernetes assumes compute is cheap and movable. Pods come up, get scheduled wherever capacity exists, run for a while, then get rescheduled or replaced. Standard WebRTC deployment patterns assume the opposite. That mismatch shows up in two specific places.
The first is port exhaustion. The conventional way to deploy WebRTC uses one UDP port per session. At OpenAI’s scale, that means tens of thousands of public UDP ports per service. Cloud load balancers were built for a handful of well-known ports, so each additional range adds operational complexity for load balancer config, health checks, firewall policy, and rollout safety. The exposed surface area also makes security audits harder. Kubernetes autoscaling clashes with the requirement to reserve large and stable port ranges, which makes elasticity brittle.
The second is state stickiness. Running one UDP port per server and demultiplexing sessions behind it solves the port problem. ICE and DTLS, however, are stateful protocols. The process that started a session has to keep receiving its packets to validate connectivity checks, complete the DTLS handshake, decrypt SRTP, and process later session changes like ICE restarts. If a packet for an existing session lands on a different process, setup fails, or media breaks.
Splitting The Relay From The Transceiver
The architecture OpenAI shipped splits packet routing from protocol termination.
A stateless relay sits at the front, presenting a small public footprint to the internet. A stateful transceiver sits behind it, owning all the heavy WebRTC state. Signaling still goes directly to the transceiver. Media enters through the relay first.
The relay’s scope is deliberately narrow. It reads enough of each packet to choose a destination, then forwards the rest as an opaque payload. Audio stays encrypted on the way through, ICE state machines stay with the transceiver, and codec negotiation happens elsewhere. From a client’s perspective, the WebRTC session looks normal in every way.
The transceiver owns the parts of WebRTC that have to remember things. ICE connectivity checks, the DTLS handshake, SRTP encryption keys, and the session lifecycle all live there. The transceiver is the endpoint that completes the handshakes and encrypts or decrypts the actual media.
An SFU, or Selective Forwarding Unit, is the standard media server architecture for WebRTC at scale. It terminates one WebRTC connection per participant and selectively forwards streams between them. The AI joins as another participant. This works well for inherently multiparty products like group calls, classrooms, and collaborative meetings. OpenAI’s workload looks different. Most sessions are 1:1, with one user talking to one model. For that kind of traffic, the SFU model adds overhead and forces backend services to behave like WebRTC peers themselves. The transceiver model lets the backend stay an ordinary service.
TURN was also considered and set aside. TURN is the standard protocol-terminating relay used for NAT traversal. The trouble is that TURN allocations add setup round-trips before media can flow, and migrating or recovering them across servers is hard. For a latency-sensitive workload, those extra round-trip matters.
Routing The First Packet
The first packet of any new session is the difficult one. Subsequent packets are easy because the relay has a mapping that says that packets from this source IP and port go to this transceiver. The first packet is what creates that mapping, so the relay has to figure out where to send it from the packet itself.
OpenAI generates the server-side ufrag during signaling. They can put whatever they want in it, so they encode routing metadata into it. The relay parses just enough of the first STUN binding request to read the ufrag, decode the routing hint, and forward the packet to the transceiver that owns the session. Every packet after the first one flows through the established session mapping, which skips the ufrag parsing step entirely.
Each transceiver in the fleet listens on a shared UDP socket, which is one operating system endpoint bound to an internal IP and port. All sessions for that transceiver multiplex behind it.
The relay’s state is purposefully tiny. It holds an in-memory map of source address to transceiver destination, plus some counters for monitoring and timers for session cleanup. If a relay instance restarts and loses the mapping, the next STUN packet rebuilds it from the ufrag. To make recovery faster, a Redis cache holds the source-to-destination mapping once a route is established. A restarted relay can look up the mapping from Redis immediately.
Global Relay and Geo-Steered Signaling
Global Relay is OpenAI’s fleet of geographically distributed relay ingress points. Geographic distribution shortens the first client-to-OpenAI hop. A packet entering the network at a relay close to the user, in both geography and network topology, has a much easier time than a packet that has to traverse the public internet to reach a distant region first.
OpenAI uses Cloudflare for geographic and proximity steering on the signaling side. The initial HTTP or WebSocket request that sets up a session is routed to a nearby transceiver cluster. The request context then determines which Global Relay ingress point gets advertised back to the client in the SDP answer.
The Go Relay Implementation
The relay is a Go service running in userspace, which is to say a regular process that reads from a regular UDP socket. OpenAI evaluated kernel-bypass frameworks and chose to stay away. Bypass raises packet throughput at the cost of operational complexity. The team’s workload fit inside what a careful Go implementation could handle.
Three implementation choices carry most of the performance load:
- SO_REUSEPORT is a Linux socket option that lets multiple workers on the same machine bind the same UDP port. The kernel then distributes incoming packets across those workers, which removes the bottleneck of a single read loop.
- runtime.LockOSThread pins each UDP-reading goroutine to a specific OS thread. Combined with SO_REUSEPORT, this tends to keep packets from the same flow on the same CPU core, which helps cache locality and reduces context switching.
- Pre-allocated buffers and minimal copying during packet parsing keep allocation overhead low and avoid putting pressure on Go’s garbage collector.
Design Tradeoffs
- The whole design is built around 1:1 sessions. If OpenAI ever wants to add multiparty features, large parts of this architecture would probably need rework.
- OpenAI also took on a custom infrastructure burden. A standard SFU comes with documentation, a community, and battle-tested patterns. The relay, the transceiver, and the coordination between them are all internal code.
- The “stateless” relay turns out to be stateless mostly in spirit. It holds an in-memory flow table and uses a Redis cache to recover that table across restarts.
- The ufrag trick depends on controlling both ends of signaling. A team that uses an off-the-shelf signaling stack might find this technique harder to adapt directly.
Conclusion
The architecture OpenAI built for voice AI is a careful response to a specific pressure. WebRTC was designed for stable servers. Modern cloud infrastructure runs on the opposite assumption. OpenAI’s team had the protocol depth to determine whether a WebRTC session needs to live in one process at all.
Their answer separates the work into two pieces. A stateless relay forwards packets near the user. A stateful transceiver, anchored in one place, owns ICE, DTLS, SRTP, and the session lifecycle. The two pieces communicate through information that’s already in the WebRTC handshake, which keeps the routing decision on the packet path itself.
Fresh dev news, AI-digested daily. Never miss a trend at devoured.fyi