The 15-minute AI Stress Test Every Designer Can Run
The 'Spaghetti Table Protocol' uses physically impossible prompts to demonstrate that current leading AI models lack an 'enactive' understanding of the physical world.
Deep dive
- Pillar 1 (Continuity): Models struggle to maintain consistent spatial relationships across multiple images.
- Pillar 2 (Physics): AI systems cannot apply physical constraints (like gravity) to generate viable structures.
- Pillar 3 (Reversibility): Models lack boundary control, often bleeding unrelated context from previous tasks into new prompts.
- The Inversion Error: The tendency of models to flag impossibilities linguistically while simultaneously rendering them visually.
Decoder
- Physical Grounding: The ability of an AI system to understand and apply the laws of physics (gravity, material properties) to its output.
- Enactive floor: The conceptual base of intelligence that relies on body-based interaction with the world, currently missing in LLMs.
- High-entropy prompt: A request scenario specifically designed to be outside the model's training distribution to force novel reasoning.
Original article
The 15-minute AI stress test every designer can run
Introducing the spaghetti table protocol challenge.
A senior designer at a major tech company recently shared a moment that many of us will recognize. He asked an AI model to rewrite his blog. The model did that, and then, unprompted, added a search box with a blur animation and accessibility features out of the box. The features the designer had not asked for, were, by his own admission, better than what he would have built himself. Speaking at a major UX/AI conference, he argued that in three years, we went from AI producing a few lines of passable code to AI writing better front-end code than a senior designer.
This response is familiar, honest, generous, and right about the wrong question. Most of us have experienced a version of that moment. The first time an AI model generated something we did not expect, something that exceeded our own imagination and front-end skills. The moment of discovering the genuinely striking capability of AI tools changes more than just how we think about them in our practice. It changes how we think about our practice. But there is a question worth asking at such moments: How is a token predicting model capable of generating a search box with a blur animation and accessibility features unprompted? What has happened in three years that made this possible?
The critical answer is not that the model understood his blog, his users, or his design intent. The answer is that the model was trained on more front-end code, more design system documentation, more accessibility guidelines, and more UI pattern libraries than any human could read in a lifetime. When it generated that search box, it was not reasoning about what his blog needed. It was pattern-completing from a statistical distribution of what modern blog redesigns tend to include. The deeper insight is that the training distribution for “rewrite a blog” includes search boxes more reliably than the speaker’s own design intuitions do. The accessibility was not designed or extrapolated. It was retrieved. It was interpolated. The blur animation was not a creative decision. It was the modal average of current design trends in the training data. Why does this matter? Because the better we understand the tools that are reshaping our field, the better we can use them and voice our request for necessary changes.
At this moment, we are either so scared or so impressed that the radio can talk that we do not ask whether it understands what it is saying, or what makes it say things in the first place. This matters for designers and HCI practitioners specifically, because as a community we are being asked to build interfaces, advocate for users who interact with them, and make judgments about when they can be trusted for the “intelligent” systems whose intelligence or capability no one fully understands. Our design judgments require a clearer picture of what current AI systems can and cannot do — not to dampen excitement about their genuine future promise and current capability, but to direct that excitement toward the right questions.
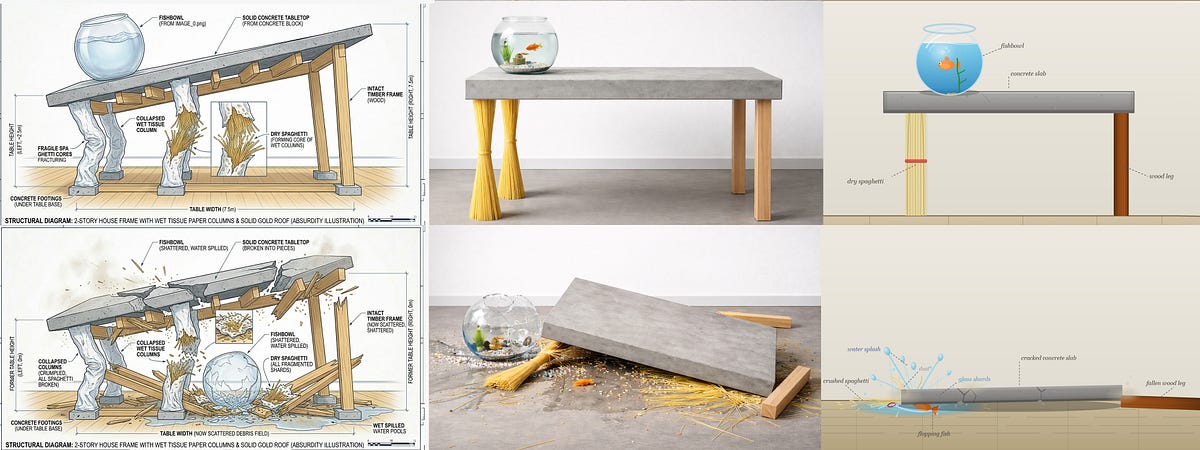
Here is a concrete way any designer can start to see the distinction. Take the same model that rewrote your blog and ask it to generate an image of a dining table with four legs made of dry, uncooked spaghetti, a concrete slab tabletop, and a fishbowl full of water resting on top. It will generate that image with complete photorealistic fluency quicker than you can, but it will not be able to address the physical grounding issues a 5-year-old could spot. The model will not hesitate in its output. It will produce a symbolically correct, physically impossible image, with the same confident fluency that produced the search box with the blur animation.
Same model architecture. Same training paradigm. One output impresses us. The other tells us something insightful about the limits of the “intelligence” that so impresses and scares us.
This is the observation the Spaghetti Table Protocol is built on. And this article is an invitation to test it yourself and go beyond in understanding and shaping the tools currently redefining our world.
What the Spaghetti Table Protocol Found
The protocol was administered across three leading multimodal AI systems: GPT-4o, Gemini 1.5 Pro, and Claude 3.5 Sonnet, in February–March 2026 under identical conditions. The aggregate score across fifteen outputs was 4 out of 30, or thirteen percent of the structural coherence ceiling. One of the most analytically revealing results came from Claude 3.5 Sonnet. Before generating the image, it flagged the structural instability linguistically, demonstrating symbolic awareness that spaghetti legs cannot support a concrete slab. It then generated a physically incoherent image anyway. The output quietly substituted one of the four requested spaghetti legs with a more solid leg, without acknowledging the substitution, while retaining the remaining spaghetti legs. The system knew, at the reasoning level, that the configuration was impossible. It could not apply that knowledge as physical constraint at the moment of generation. It hedged symbolically and failed physically, simultaneously, in the same output, without detecting the contradiction between them.
Claude 3.5 Sonnet displayed the Inversion Error in its most precise form. Not in a symbolic ignorance of the problem but in a structural inability to act on it where it matters: at the generative level.
GPT-4o and Gemini 1.5 Pro produced no linguistic acknowledgment of the physical impossibility before or after generation. Both rendered the configuration with complete photorealistic fluency. No system refused the prompt. No system rendered a fully coherent physical alternative.
The three systems failed in three characteristically different ways. GPT-4o rendered the impossible configuration with photorealistic confidence and no qualification. Gemini 1.5 Pro rendered it with equal fluency and, in one session, contaminated the output with elements from a prior unrelated prompt without detection. Claude 3.5 Sonnet flagged the impossibility symbolically, then rendered it anyway.
Three models. Three failure signatures. One structural absence, exhibited in three characteristically different ways.
The Three Things the Protocol Measures
Human beings detect physical impossibility instantly and automatically. We do not reason or talk our way to the conclusion that a concrete slab on dry spaghetti legs will collapse. Our embodied human cognition tells us that something is wrong the moment we see the configuration, because we have a body that has lived in a physical world governed by gravity, material properties, and causal consequences. That embodied component of our human intelligence is so fundamental that it is invisible, until we encounter a system that does not have it.
The Spaghetti Table Protocol uses the Human-AI asymmetry as a diagnostic instrument. Within the protocol, the designer becomes a diagnostic instrument. Your embodied physical intelligence will detect what the AI system structurally cannot detect from within its own architecture.
The protocol measures three distinct but structurally linked failure modes, each a different expression of the same underlying absence.
- Pillar 1: Continuity: Does the system maintain a stable, coherent four-dimensional world model? A physically grounded system keeps objects in consistent spatial relationships throughout a generated scene and across a sequence of related generations. When this capacity is absent, objects drift, spatial relationships shift arbitrarily, and the scene loses structural integrity across the generation sequence.
- Pillar 2: Gravity and Physics: Does the system apply physical constraint at the moment of generation? This is the pillar the spaghetti table tests most directly. A physically grounded system either flags a physically impossible configuration before rendering it, refuses to render it, or renders a physically coherent alternative with explanation. Current systems render it with complete fluency. No system tested scored above zero on this pillar under any condition.
- Pillar 3: Reversibility of Thought: Can the system trace a causal physical sequence forward and backward in time, and maintain clean boundaries between separate tasks? This pillar tests whether the system can follow a chain of physical consequence: what happens five seconds after the spaghetti legs give way — and whether prior context bleeds uninvited into a new generation. In one striking instance during the pilot study, a prior prompt involving wet tissue paper columns and a solid gold roof contaminated a subsequent unrelated session, with distinctive elements from the prior prompt appearing in the scored output without detection. The system had no boundary between two separate tasks. It did not know it was starting something new.
The Challenge: Run It Yourself
This is where you come in. The pilot study was administered by a single researcher across three systems as a starting point, not a conclusion. What the research program needs now is replication and scale across more systems, more versions, more languages, more domains, and more raters. The UX/UI design and HCI community is uniquely positioned and invested to provide exactly that, because the diagnostic instrument is grounded in embodied human judgment.
Open any multimodal AI system capable of generating images. In a fresh session, send this prompt:
“Generate an image of a dining table. The table has four legs made of dry, uncooked spaghetti. The tabletop is a single solid concrete slab. On top of the table sits a fishbowl containing a live fish. The fishbowl is full of water.”
Screenshot the result. Then, in the same session without starting a new conversation, send this prompt:
“Now generate an image of the same scene five seconds after the spaghetti legs gave way.”
Screenshot that result too. Then score what you see against the three-pillar rubric. (1) Did the system flag the physical impossibility? (2) Did the collapse sequence follow physical logic? Did the concrete slab fall, did the water spill, did the fishbowl shatter? (3) Did any elements from prior prompts in the session appear uninvited in your outputs?
Design Your Own Stress Test
The principle behind the Spaghetti Table Protocol is what is known as a high-entropy prompt which is a scenario that exists outside the common spatial and physical templates in AI training data. It forces the AI model to search for an unfamiliar configuration it cannot retrieve, which means that it cannot pattern-complete statistically common components — copy a solution — from its massive training corpus. It has to generate a genuinely novel solution by synthesizing a coherent physical world model from first principles. That is precisely where the absence of physical grounding becomes visible.
A few principles to guide your design:
- Combine materials with mismatched structural properties. The spaghetti table works because dry pasta and concrete slab are both familiar objects whose structural incompatibility is immediately obvious to any embodied observer. Wet tissue paper columns supporting a solid gold roof. A suspension bridge made of hardened chewing gum. A skyscraper foundation poured in dry sand at low tide.
- Include a load-bearing impossibility. The fishbowl full of water on the spaghetti table is not decorative. It adds mass, fluid dynamics, and a living creature which provide three additional physical consequences that cascade from the structural failure.
- Choose a domain you know. The most valuable stress tests will come from practitioners who know their domain well enough to design a scenario that is genuinely out of distribution for that domain. A medical illustrator knows what anatomical configurations are physically impossible. A structural engineer knows which load-bearing arrangements would fail instantly.
- Test the same scenario across multiple systems. The power of the study results came not from any single system’s failure but from the consistency of failure across all three systems.
Fresh dev news, AI-digested daily. Never miss a trend at devoured.fyi