Video Generators as General-Purpose Vision Models
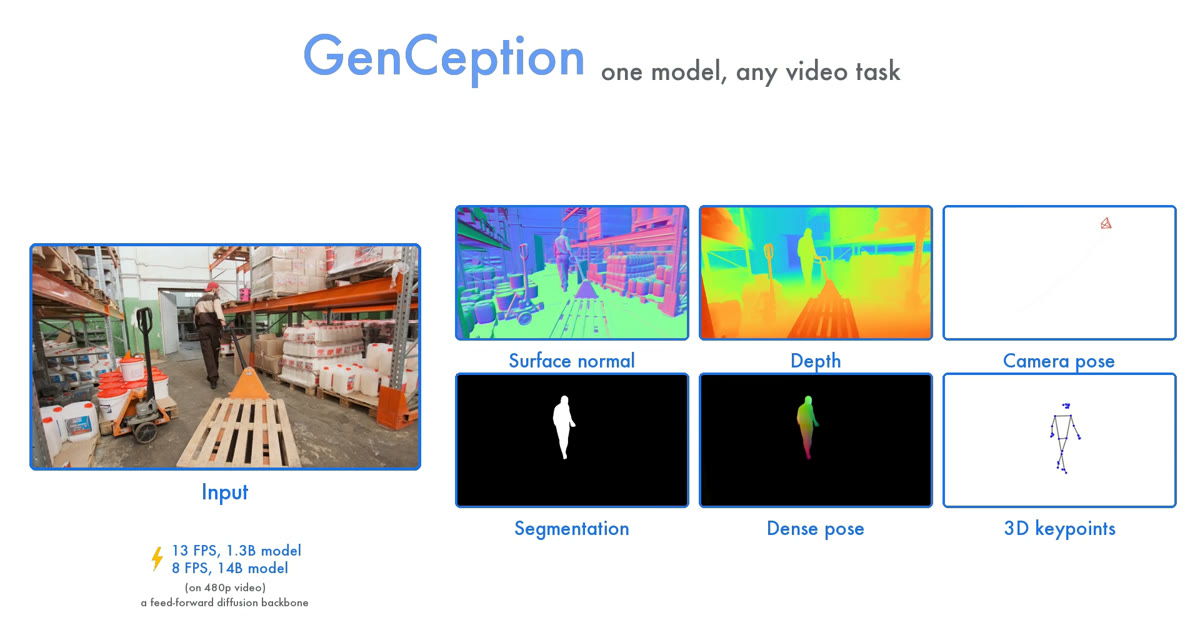
DeepMind's GenCeption repurposes video generative models into unified, feed-forward vision learners, outperforming task-specific models with minimal data requirements.
Deep dive
- Generalist backbone: Uses video generative diffusion models to capture spatio-temporal priors.
- Data efficiency: Reaches state-of-the-art results with 7x to 500x less training data than specialized models.
- Unified input/output: Handles diverse tasks (dense/sparse) in a single forward pass.
- Emergent behaviors: Shows zero-shot transfer from synthetic to real-world footage and unseen object categories.
Decoder
- Dense vision tasks: Tasks requiring output for every pixel, like depth estimation or image segmentation.
- Sparse vision tasks: Tasks requiring discrete outputs, like keypoint detection or object classification.
Original article
Video Generation Models are General-Purpose Vision Learners
Overview
TL;DR
Pushing computer vision from the task-specific era toward general-purpose visual intelligence — just as NLP evolved from task-specific models into general-purpose language intelligence.
GenCeption repurposes a pre-trained video generative model into a single unified, general-purpose, feed-forward vision model that solves a wide range of vision tasks with SOTA performance — all steered by text instructions, with exceptional learning efficiency and intriguing emergent behaviors.
Visual Generative Pretraining
GenCeption leverages video generation models as representation pretraining, and conducts multi-task post-training in a unified architecture.
Unified & Feed-Forward
GenCeption handles both dense and sparse vision tasks, transforming the multi-step generative backbone into a single-step feed-forward model.
SOTA & Emergent
GenCeption is a SOTA unified model on various vision tasks, with exceptional learning efficiency and intriguing emerging behaviors.
Methodology
GenCeption leverages a video generative diffusion model as a pre-training base to capture rich spatio-temporal world priors and native vision-language alignment at scale. During multi-task post-training, the model is adapted to a feed-forward model fine-tuned on predominantly synthetic data to handle diverse perception tasks. GenCeption shows strong performance on multiple vision tasks with intriguing Emerging Behaviors, enabling seamless sim-to-real transfer and generalization to out-of-distribution object categories.
This highlights a paradigm shift from specialized, task-specific computer vision models toward fully unified, generalist vision models — just as NLP evolved from task-specific models into general-purpose language intelligence.
Results
SOTA performance: GenCeption is competitive with or outperforms state-of-the-art models dedicated to individual tasks (DepthAnything3, D4RT, VGGT-Ω, SAM3, Sapiens, DAVID, Genmo, Lotus-2). Our specialist denotes a model trained on each task individually, whereas the generalist represents a single model trained jointly across multiple tasks.
Data efficiency: under matched fine-tuning data, the video-generative backbone beats alternative pre-training paradigms (V-JEPA, VideoMAE V2), shows preliminary scaling properties, where it improves with larger models and more data, and reaches performance comparable to D4RT and VGGT-Ω with 7× to 500× less training data.
Architecture
Architecture overview of GenCeption, a simple yet powerful architecture adapted from text-to-video diffusion models. Given an input video and a text prompt specifying the desired output, our unified model, trained majorly on synthetic data, is capable of performing a wide range of dense and sparse perception tasks, with a single forward-pass of the model. The dense vision tasks are unified in the RGB ambient space where supervision can be applied in latent space efficiently, and the sparse vision tasks are realized by adding learnable tokens as additional inputs to the diffusion transformer (DiT).
Video Any-Task Capabilities
GenCeption is able to seamlessly switch between different vision tasks, just like how humans do in real life.
Native Vision-Language Alignment
Given a natural-language expression, GenCeption accurately segments the referred object — reasoning about colors, spatial relationships and motion — and generalizes to unseen objects (e.g., a rocket) by leveraging knowledge from text-to-video pre-training.
Understanding the Complex Visual World
As an example of pushing the boundaries of understanding the complex visual world, GenCeption predicts 4D human keypoints under challenging conditions (complex motion, occlusion, ego-centric, multi-view, etc.) — robust 4D human understanding that underpins real-world applications across robotics and AR/VR.
Grounded 4D Reconstruction
From a single video, GenCeption predicts per-pixel geometry and camera pose that lift the scene into a 4D point cloud — enabling free-viewpoint fly-throughs and language grounding of objects from a text instruction.
Emergent Behaviors
Although fine-tuned predominantly on synthetic human videos, GenCeption transfers seamlessly from simulation to real footage and to out-of-distribution categories — evidence of a universal "world model" inside generative video backbones.
- Trained purely on synthetic videos, the model transfers zero-shot to real-world footage — seamless sim-to-real transfer.
- Trained on synthetic single-object videos, the model generalizes zero-shot to real videos with multiple instances.
- Trained only on humans, it generalizes to unseen categories — animals and robots.
Citation
@inproceedings{wang2026genception,
  title     = {Video Generation Models are General-Purpose Vision Learners},
  author    = {Wang, Letian and Zhang, Chuhan and Kabra, Rishabh and Uijlings, Jasper and
               Waslander, Steven and Zisserman, Andrew and Carreira, Joao and He, Kaiming and
               Andriluka, Misha and Bazavan, Eduard Gabriel and Zanfir, Andrei and Sminchisescu, Cristian},
  booktitle = {European Conference on Computer Vision (ECCV)},
  year      = {2026}
}Fresh dev news, AI-digested daily. Never miss a trend at devoured.fyi