Why DoorDash, Instacart, and Uber Eats Integrated LLMs Into Search Three Different Ways
DoorDash, Instacart, and Uber Eats all integrated LLMs into their search stacks differently based on their existing infrastructure rather than model capabilities.
Deep dive
- DoorDash: Uses LLMs as an offline enrichment layer to keep the runtime strictly classical and graph-driven.
- Instacart: Splits traffic between cached head queries and real-time fine-tuned models for tail queries.
- Uber Eats: Adopts a shared embedding space using Qwen for cross-vertical and cross-lingual retrieval.
- The 'depth' of LLM integration into the runtime is determined by legacy infrastructure requirements.
- Hybrid systems combining traditional ANN indexes with LLM-based understanding remain the industry standard.
Decoder
- Two-tower retrieval: A neural network architecture where two separate encoders (query and document) map input to a shared vector space for similarity searching.
- HNSW (Hierarchical Navigable Small World): A graph-based data structure used to perform high-performance approximate nearest neighbor searches.
- RAG (Retrieval-Augmented Generation): Providing an LLM with external, relevant data context to ground its output and reduce hallucinations.
- Matryoshka Representation Learning (MRL): A training technique that allows a single embedding model to produce representations of varying lengths while maintaining utility.
Original article
Why DoorDash, Instacart, and Uber Eats Integrated LLMs Into Search Three Different Ways
Over the last few years, three of the biggest food delivery companies rebuilt their search systems around LLMs. DoorDash, Instacart, and Uber Eats were solving the same problem of trying to understand a user’s intent when they type something in search. They were also accessing more or less the same research base. And yet, the architectures they shipped look quite different from each other.
That divergence is one of the most interesting aspects of modern development using LLMs. Once we understand why each company landed where it did, we will have a mental model for thinking about how AI can be integrated into any production system.
Adding an LLM to an existing stack comes down to one question: how deeply should the LLM reach into the runtime?
Ultimately, DoorDash, Instacart, and Uber Eats each answered that question differently, and the specific LLM each chose was secondary. The infrastructure they already had in place is what determined the answer.
In this article, we will walk through their differing solutions and try to make sense of their choices and understand the pattern behind them.
Disclaimer: This post is based on publicly shared details from various sources. References are present at the end. Please comment if you notice any inaccuracies.
The Problem
Type “something healthy for a rainy evening” into a food delivery app and watch what comes back. The result we get today is somewhere between useful and impressive. The same query five years ago might have returned a random jumble of items, because keyword search treats the words as a bag of tokens rather than as an intent, and the query offers little for keyword matching.
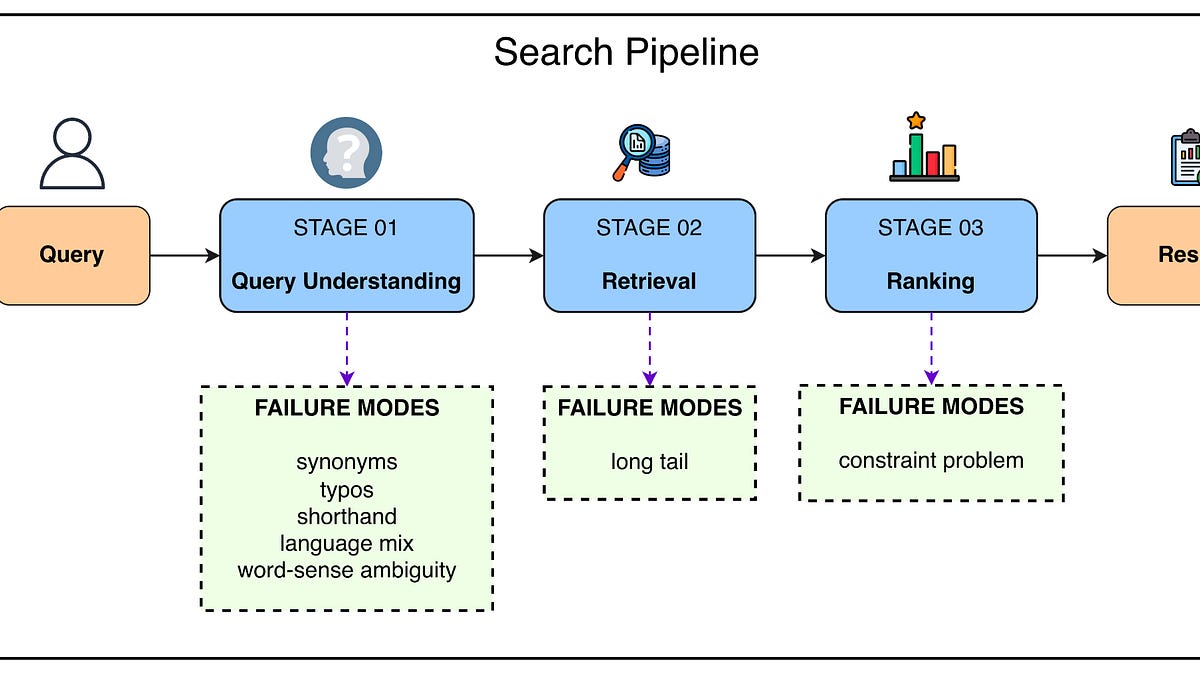
This pattern repeats across several common failure modes in food search. For example:
- Synonyms: “Soda” and “soft drink” describe the same product, but a keyword engine treats them as different tokens.
- Typos: “Mozzarela” should retrieve mozzarella results, but the spelling mismatch breaks the lookup.
- Shorthand: “Gf pizza” meaning gluten-free pizza requires the system to recognize an abbreviation as a synonym for the full phrase.
- Language mix: The Spanish word “pan” means bread, while the English word “pan” means a cooking vessel, so a bilingual search bar has to disambiguate.
- Word-sense ambiguity: “Apple” the fruit and “Apple” the company share the same spelling but mean different things, and the right answer depends on context.
Two harder problems lie beneath this:
- The long tail: Grocery and restaurant platforms see an enormous number of unique queries. Any specialized model trained on conversion data struggles with queries that appear only a handful of times, because rare queries are rare by definition.
- The constraint problem: A query like “vegan chicken sandwich” has a hard constraint inside it, and similarity-based retrieval might return a chicken sandwich that violates the constraint, because the similarity score still looks close. Dietary restrictions, allergens, and quantity filters all sit in this bucket.
DoorDash
DoorDash already had a knowledge graph for items and restaurants when LLMs became viable for production. The graph held structured attributes for every item, including dish type, dietary preference, cuisine, brand, and flavor.
Their approach was to use LLMs to enrich this graph offline by extracting attributes from SKU data, and to use LLMs at runtime only for parsing queries into chunks that could link back to the graph. Retrieval itself stayed keyword and graph-driven.
Consider the query “small no-milk vanilla ice cream.” The LLM segments it into three chunks.
- “small” is a quantity attribute.
- “no-milk” is a dietary preference attribute that maps to the canonical label “dairy-free.”
- “vanilla ice cream” splits further into a dish type (”ice cream”) and a flavor (”vanilla”).
Each chunk is then linked to a specific field in the knowledge graph. The dietary preference becomes a hard filter, so only dairy-free items get retrieved. The flavor becomes a soft preference for ranking. The dish type narrows the candidate pool.
What distinguishes DoorDash’s approach is how they constrain the LLM’s outputs.
They use retrieval-augmented generation as a guardrail rather than as a generator. For each query segment, an approximate nearest neighbor lookup retrieves the top 100 closest taxonomy concepts from the existing graph. The LLM is then prompted to pick from that list rather than invent labels. This is a clever inversion of the usual RAG pattern, where RAG typically injects context into a generator. Here, RAG defines the entire output space, so the system only ever produces concepts that the rest of the design already knows how to handle.
Instacart
When Instacart’s engineers first investigated an off-the-shelf LLM to categorize the search query “protein,” the model returned chicken, tofu, beef, and other high-protein foods.
The answer is reasonable by any reading of the English language. The problem is that Instacart’s actual users, when they type “protein,” are looking for protein bars and protein powders. The model’s general world knowledge and the company’s specific user behavior were pulling in different directions.
Instacart’s strategy is layered across three approaches:
- Context engineering: Retrieval-augmented generation pulls Instacart-specific context (top-converted categories, historical conversion data, catalog details) into the prompt before the LLM sees a query.
- Post-processing guardrails: Semantic similarity filters drop LLM outputs that drift away from the original query.
- Fine-tuning: For the most advanced tasks, the team fine-tunes Llama-3-8B on Instacart’s proprietary data, so domain knowledge gets baked directly into the model weights.
The serving architecture splits along the head-versus-tail distribution. Head queries hit an offline RAG-and-cache pipeline that is latency-tolerant and deeply context-engineered, while tail queries hit a real-time fine-tuned Llama-3-8B model that keeps latency under 300ms through adapter merging, H100 GPUs, and autoscaling.
Uber Eats
Uber Eats faced the same problem the others did, plus a complication. They run across multiple verticals, including restaurants, grocery, and retail, across multiple markets, and across a long list of languages. Their goal was a single retrieval system that handled every vertical, every market, and every language with one consistent embedding space.
The architecture they decided on is a classic two-tower setup, where a query encoder and a document encoder each produce vectors in a shared space, and matching is done by similarity in that space.
The twist is in what sits inside each tower, because both towers use a fine-tuned Qwen LLM as their backbone embedding layer. The query tower runs online, embedding each incoming query in real time, while the document tower runs offline and pre-embeds billions of documents into an HNSW vector index.
Out of the box, Qwen brings world knowledge and cross-lingual capability. Fine-tuning on Uber’s proprietary query-document interactions teaches the embedding space what Uber Eats users actually care about, and this is what gives the system its domain alignment.
Integration Depth
If we line up the three companies on a single axis labeled “how deeply does the LLM sit in the runtime,” the pattern provides some insight:
- DoorDash sits on the left, with the LLM enriching the catalog offline and parsing queries with constrained outputs while the runtime stays mostly classical.
- Instacart sits in the middle, with LLMs handling query understanding through offline RAG for the head queries and a fine-tuned Llama-3-8B for the tail, while retrieval downstream is still traditional.
- Uber Eats sits on the right, with a fine-tuned Qwen as the embedding backbone running for every query and pre-baked into every document vector.
The lesson would be that before asking which LLM to use for some task, the better question is where in an existing stack an LLM would actually help. Each company’s position on the spectrum traces back to the infrastructure it already had.
Conclusion
Three universal tradeoffs survived every architecture:
- Hybrid systems are the default everywhere. Classical retrieval, knowledge graphs, and ANN indexes still do most of the work.
- World knowledge from a pre-trained model is just a head start. Domain context still has to be injected somewhere, through RAG, fine-tuning, or both.
- Guardrails are an important part of every production LLM system. Constrained vocabularies, similarity filters, and taxonomy enforcement quietly determine whether outputs stay aligned with the catalog.
Fresh dev news, AI-digested daily. Never miss a trend at devoured.fyi