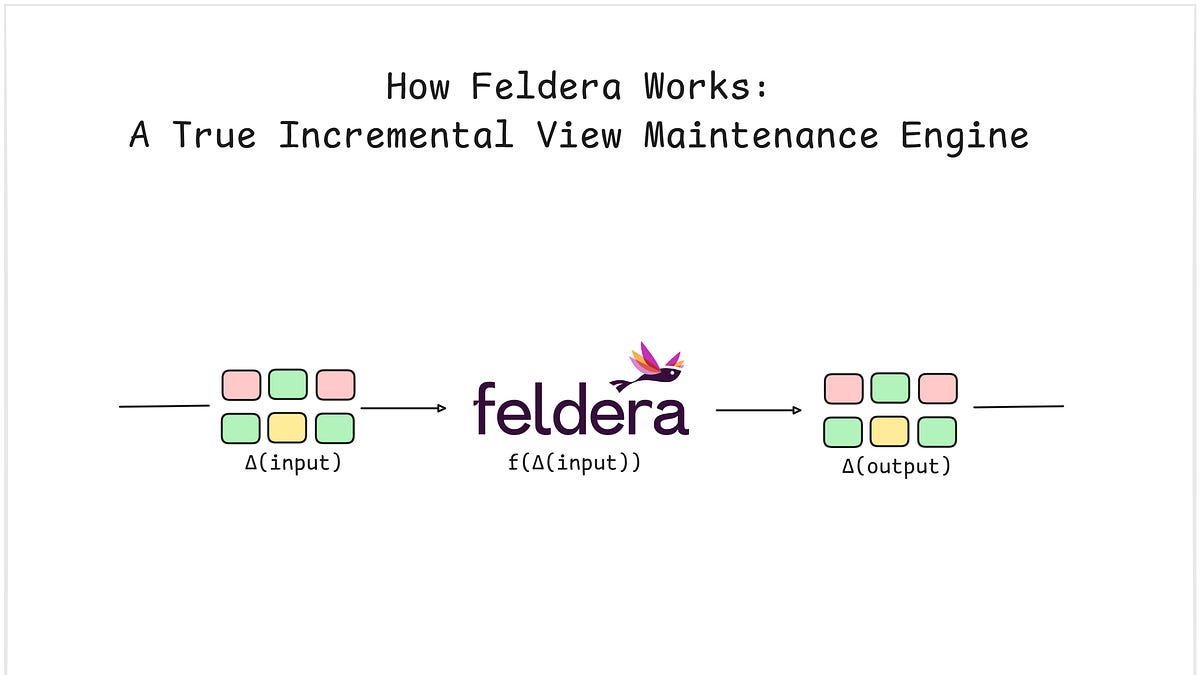
How Feldera Works: A True Incremental View Maintenance Engine
Feldera achieves low-latency continuous analytics by treating data streams as evolving relational views using incremental delta propagation instead of recomputation.
Deep dive
- Streaming systems often struggle with joins and complex aggregations due to state recomputation costs.
- Feldera maps SQL operators to DBSP circuits that handle Z-set deltas.
- Inserts are +1, deletes are -1, and updates are -1/+1 operations.
- Complexity is O(Δ), meaning performance depends on the number of changed rows, not table size.
- The synchronous execution model ensures deterministic, batch-like consistency for continuous pipelines.
Decoder
- Z-set: A mathematical representation of a set where elements have associated integer counts, used here to represent relational deltas.
- Incremental View Maintenance (IVM): A technique that updates a materialized view based only on the changes to the underlying source data, rather than rebuilding the view from scratch.
Original article
How Feldera Works: A True Incremental View Maintenance Engine
Most streaming systems excel at event processing but struggle with relational queries involving joins or multi-stage aggregations. Feldera changes the game by treating streams as incremental relational views, using DBSP to propagate deltas efficiently and avoid recomputation. This article explores Feldera’s incremental execution model and why it scales for complex analytics.
Challenges with Complex Relational Queries
Streaming SQL engines such as Apache Spark Structured Streaming and Apache Flink work well for simple workloads like filters and basic aggregations, where updates can be applied incrementally and the work scales roughly with the incoming data rate.
However, real-world analytical pipelines often involve multi-stage transformations, joins with mutable dimensions, and nested aggregations. In such cases, even incremental updates can amplify intermediate changes, increasing computation and memory usage.
Furthermore, their execution interface fails to deliver the core promise of SQL, its simplicity and ease of use.
Relational queries operate on relations, not events. Efficient continuous query execution therefore requires a different abstraction: algebraic delta propagation.
This is precisely where Feldera diverges.
Inside Feldera: DBSP and Algebraic Delta Propagation
Feldera is built on DBSP (Database Stream Processor), an execution engine for composing incremental computations. DBSP represents queries as circuits built from a small set of primitive operators that can express arbitrarily complex SQL pipelines.
It basically combines the concepts from streaming engines and databases to give one simple solution like a live database.
In Feldera, every update is represented as a relational delta:
- Insert → +1 row
- Delete → −1 row
- Update → −1 old row, +1 new row
This delta-based approach lets Feldera precisely capture all relational changes, including inserts, updates, deletes, corrections, and late-arriving data. Streams are not treated as append-only logs; instead, they are modeled as streams of relational differences, enabling full relational semantics in continuous pipelines.
Feldera compiles SQL queries into DBSP operators by translating relational changes into streams of Z-sets, an algebraic representation of relational deltas. Each relational operator (projection, filter, join, union, aggregation, etc.) becomes a differentiable streaming operator that consumes and produces Z-sets, incrementally propagating changes through the circuit.
Each operator maintains indexes over its input state, mapping keys to rows or partial aggregates. This allows operators to:
- Quickly look up only the rows affected by a change (critical for joins, aggregations, and filters).
- Apply inserts, deletes, and updates without scanning the entire operator state.
- Produce Δ(output) efficiently for downstream operators.
Computation is driven entirely by change propagation, not by event arrival.
Feldera ensures that execution cost scales with the size of the change (O(Δ)), not with the total table size or query depth. This is a key reason why Feldera is extremely resource-efficient.
At the algebraic level, each operator computes output deltas purely as a function of input deltas.
Δ(output) = f(Δ(inputs))The same principle applies to joins and aggregations, e.g. algebraic join delta rule:
Δ(A ⋈ B) = (ΔA ⋈ B) ∪ (A ⋈ ΔB) ∪ (ΔA ⋈ ΔB)If an aggregation feeds into a join, and that join feeds into another aggregation, each stage propagates only deltas. This allows arbitrarily deep relational pipelines to maintain:
Total cost ∝ total delta propagation
Synchronous Streaming Execution
DBSP executes computations using a synchronous streaming model, where updates propagate through the circuit in deterministic steps. This ensures that query results remain consistent and reproducible, preserving the same semantics one would expect from batch SQL execution even as new data continuously arrives.
This is particularly important for correctness-critical workloads such as financial processing, compliance analytics, and machine learning feature pipelines.
Computational Complexity
Feldera's asymptotics are guaranteed by the math, design and implementation.
This means Feldera’s performance depends only on how much data changes. This keeps CPU usage low, reduces memory pressure, delivers predictable latency, and enables linear scalability; even for complex continuous workloads.
References
- DBSP: Automatic Incremental View Maintenance for Rich Query Language
- Can your incremental compute engine do this?
- Incremental Database Computations
- A synchronous streaming model
- Can Math simplify incremental compute?
Fresh dev news, AI-digested daily. Never miss a trend at devoured.fyi