Compute Optimal Tokenization
Training 1,300 models revealed the industry-standard 20 tokens per parameter scaling law is a BPE tokenizer artifact, not a universal constant.
Deep dive
- The authors trained 1,300 models across varying model sizes and compression rates (bytes per token) to systematically derive tokenizer-agnostic scaling laws
- The widely-cited Chinchilla law (20 tokens per parameter) is shown to be an artifact of specific BPE tokenizers, not a fundamental property of neural scaling
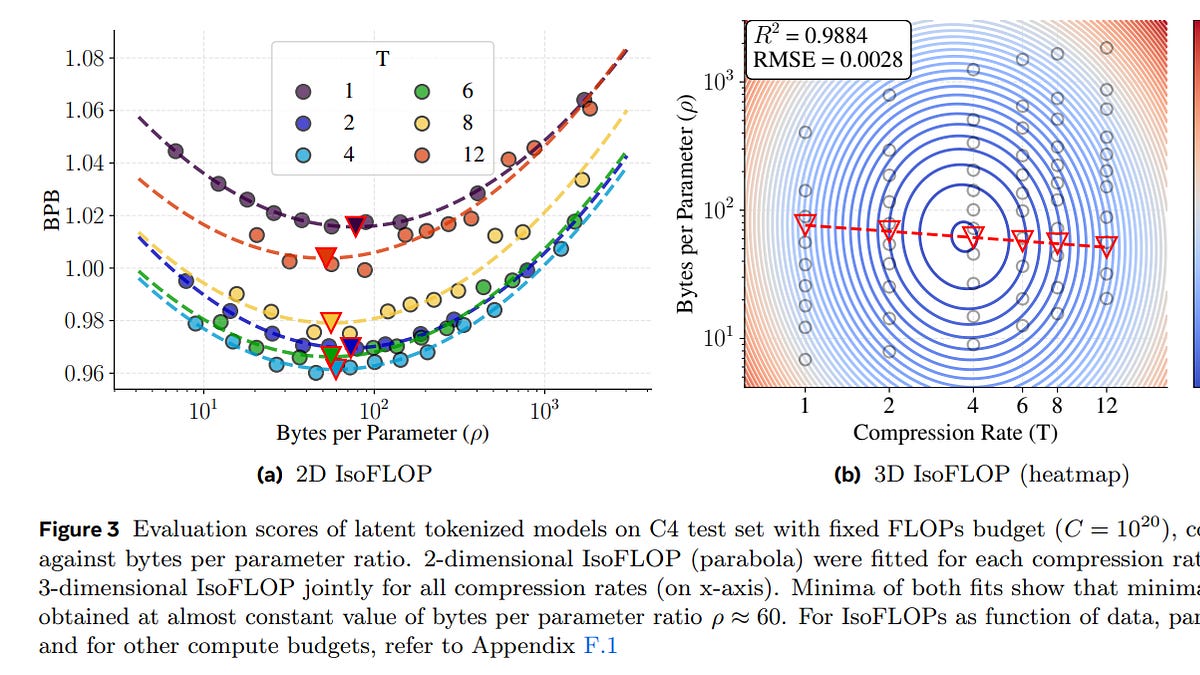
- Training data should scale proportionally to model parameters in bytes, not tokens, to account for variable information density across languages and tokenizers
- Optimal compression rate is compute-dependent: as FLOP budgets increase, lower compression (more bytes per token) becomes more efficient
- This framework provides a path to more efficient multilingual foundation models by optimizing tokenization as a dynamic scaling variable rather than a static preprocessing choice
- Project code and interactive tools available at co-tok.github.io for exploring compression-compute tradeoffs
Decoder
- Byte-Pair Encoding (BPE): A tokenization algorithm that iteratively merges the most frequent pairs of bytes/characters into single tokens. Used by most LLMs including GPT and LLaMA.
- Chinchilla scaling laws: Research from DeepMind establishing that optimal LLM training uses roughly 20 tokens per model parameter. Named after their 70B parameter Chinchilla model.
- Compression rate: In this context, the information density of tokens measured in bytes per token. Higher compression means each token encodes more raw information.
- FLOP budgets: Total floating-point operations allocated for training. Determines the compute cost/scale of a training run.
Original article
Compute Optimal Tokenization
Authors: Tomasz Limisiewicz, Artidoro Pagnoni, Srini Iyer, Mike Lewis, Sachin Mehta, Alisa Liu, Margaret Li, Gargi Ghosh, Luke Zettlemoyer
Paper: https://arxiv.org/abs/2605.01188v1
Code: https://co-tok.github.io
TL;DR
WHAT was done? The authors systematically derived compression-aware neural scaling laws by training nearly 1,300 models to determine how information granularity (bytes per token) impacts optimal compute allocation.
WHY it matters? This work proves that the widely accepted heuristic of scaling models by 20 tokens per parameter is an artifact of specific subword tokenizers. Establishing a tokenizer-agnostic scaling law based on bytes provides a robust framework for maximizing compute efficiency across diverse languages and modalities.
Executive summary: For research teams optimizing large-scale pre-training runs, the tokenization scheme is often treated as a static preprocessing step. This paper reframes tokenization as a dynamic scaling variable. By optimizing the "compression rate" (information density), the authors demonstrate that training data should scale proportionally to model parameters in bytes, not tokens. Furthermore, they reveal that the optimal compression rate is compute-dependent, requiring lower compression as FLOP budgets scale up, thus offering a new blueprint for training highly efficient, massively multilingual foundation models.
Details
The Tokenization Artifact Bottleneck in Neural Scaling
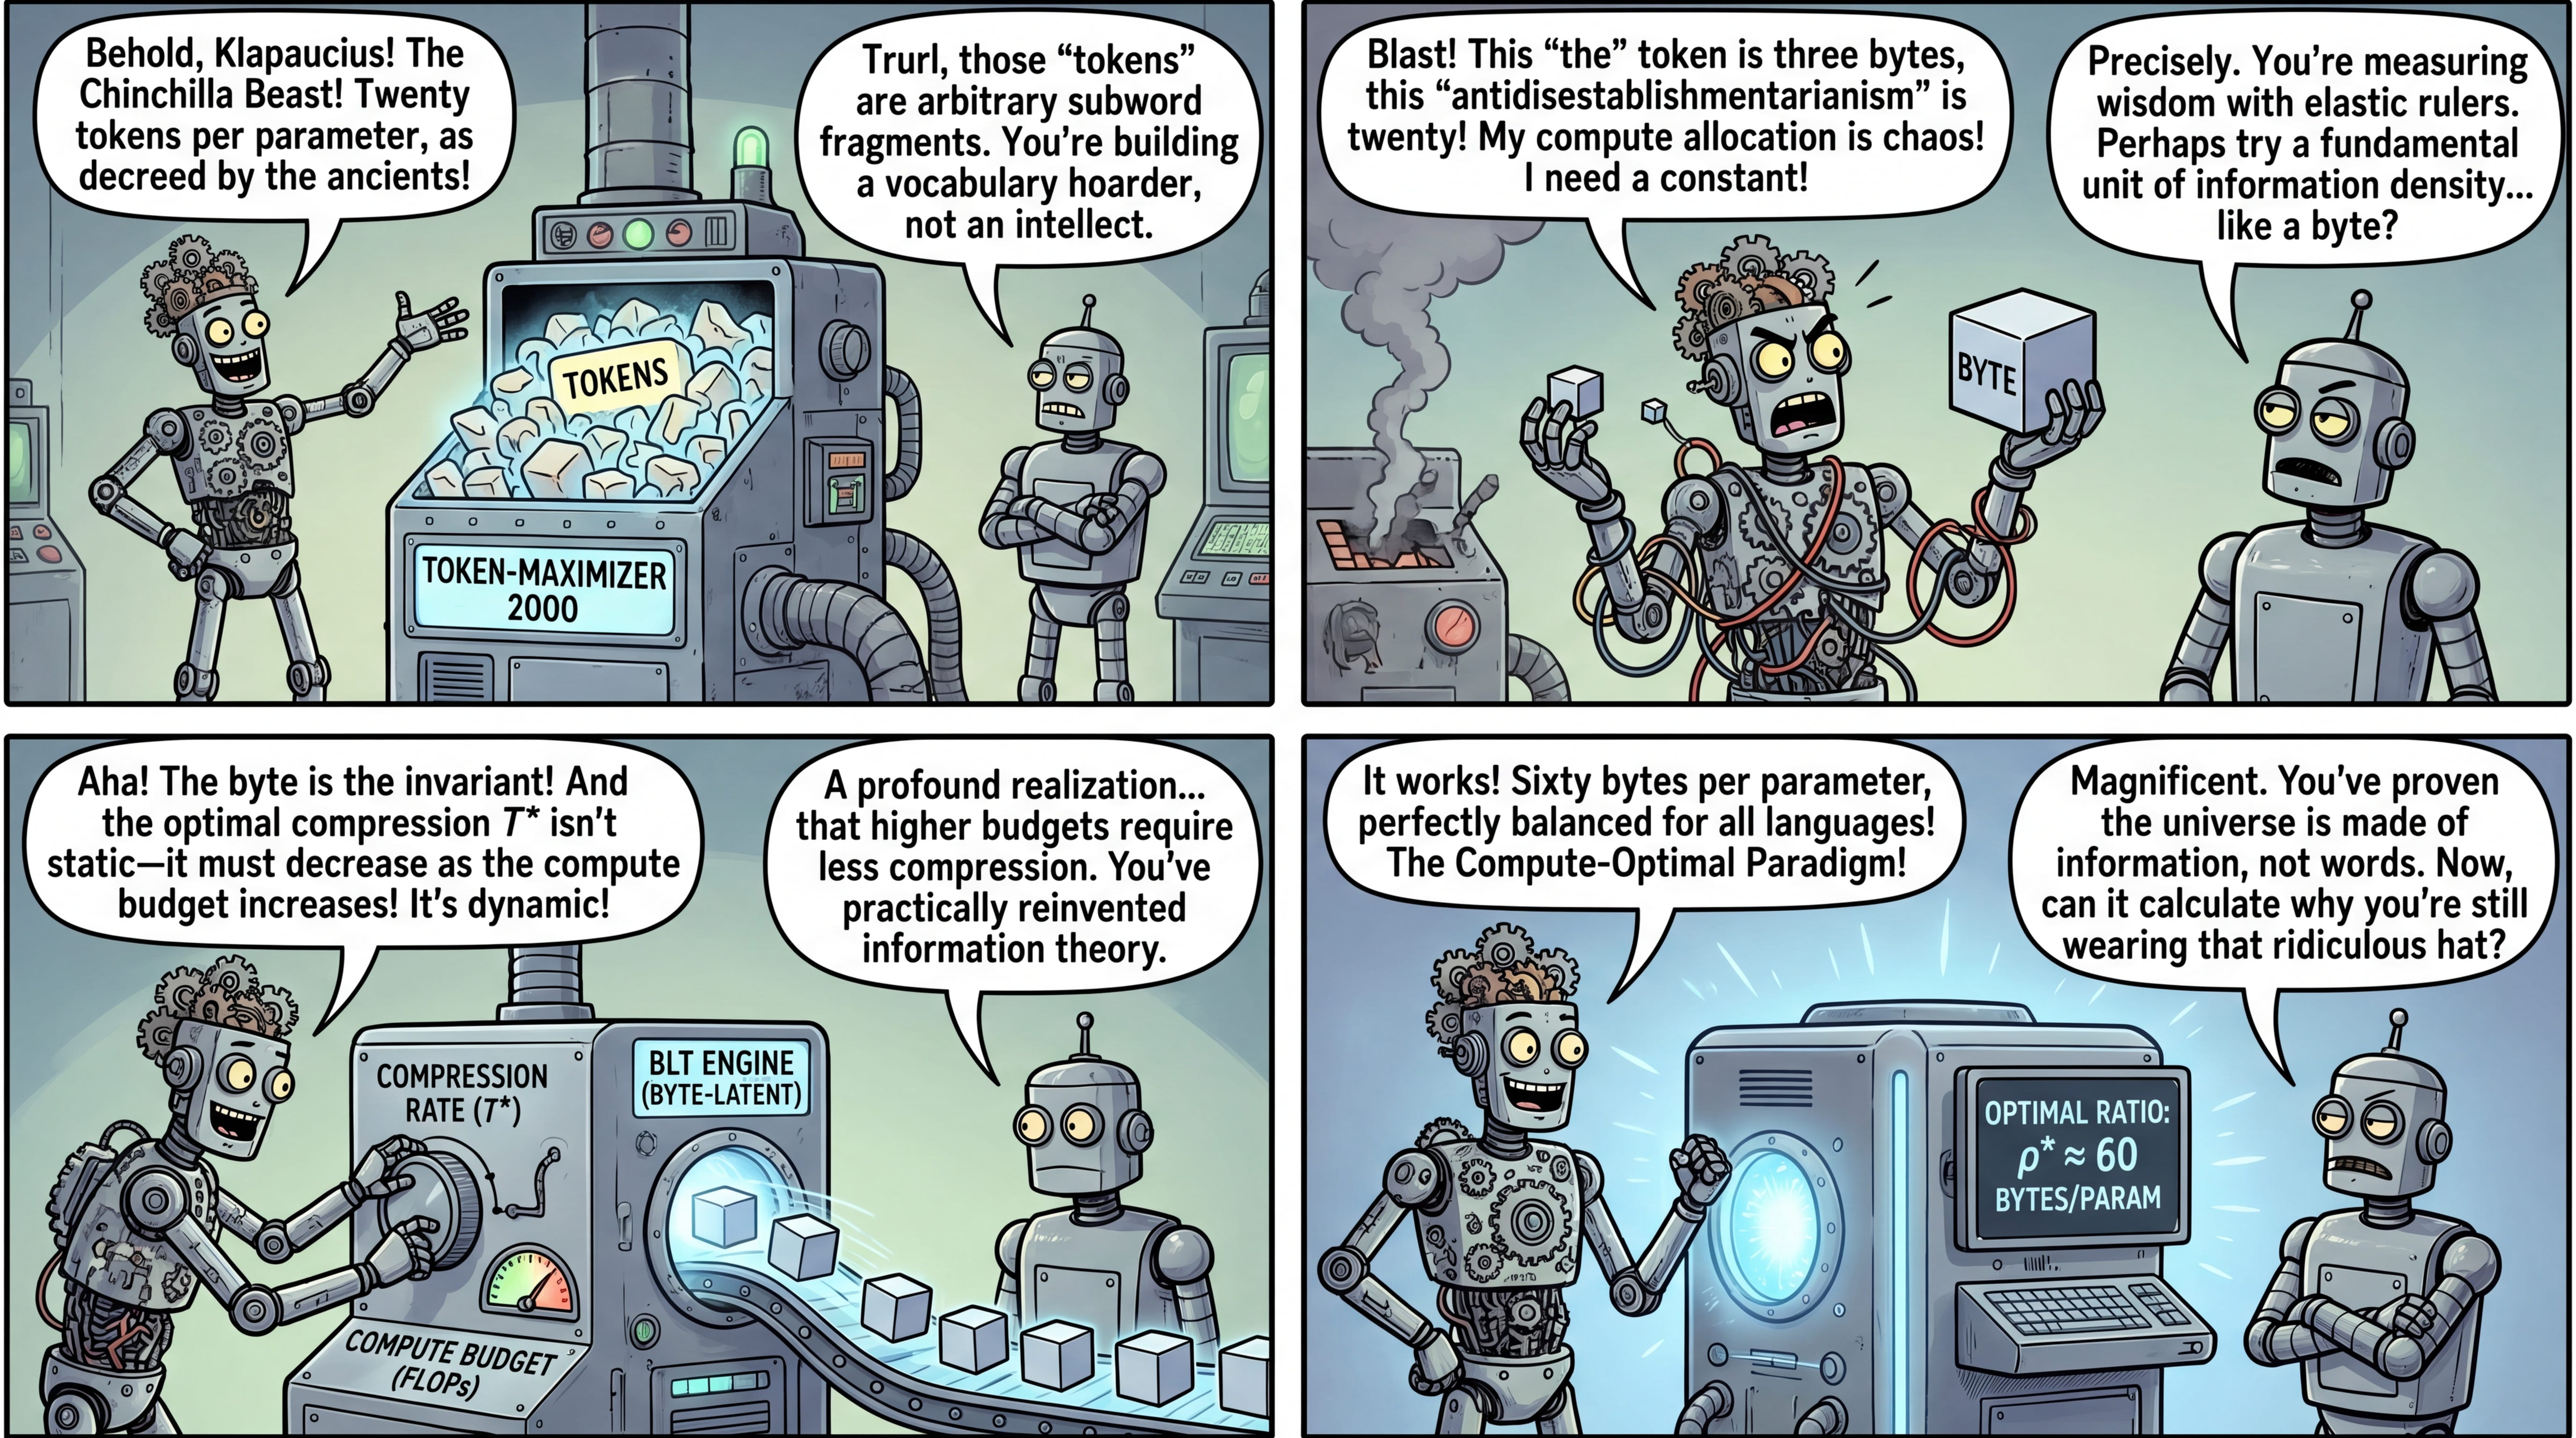
Foundation model scaling is largely governed by established scaling laws, most notably the heuristic derived in Training Compute-Optimal Large Language Models (Chinchilla), which posits an optimal ratio of approximately 20 training tokens per model parameter. However, a critical blind spot in this heuristic is its reliance on a fixed tokenization scheme. Expressing data volume strictly in tokens ignores the variable information density that each token represents, essentially binding fundamental scaling behavior to the arbitrary mechanics of Byte-Pair Encoding (BPE) tokenizers. This study isolates the token as a variable to identify the true invariant in scaling behavior, exposing the extent to which popular tokenizers inherently skew compute allocation.
Fresh dev news, AI-digested daily. Never miss a trend at devoured.fyi