Introducing the MySQL Analytical Replica (Parquet + DuckDB)
DBTrail is an open-source tool that enables analytical reporting on MySQL by streaming binlogs into Parquet files, allowing for high-performance querying via DuckDB.
Deep dive
- DBTrail captures MySQL binlog data to create consistent analytical snapshots in Parquet format.
- It requires no plugins or agents on the MySQL database, supporting AWS RDS and Aurora.
- The tool uses DuckDB for SQL execution, allowing local analysis of the Parquet files.
- It provides row-level history, enabling 'time-travel' queries to view table state at specific points in time.
- A generated
views.sqlfile provides a consistent interface for querying the latest snapshot. - Benchmarks show it significantly outperforms production MySQL for group-by operations on large datasets.
- The system is designed to avoid the 'pipeline' overhead typically associated with tools like Debezium, Airbyte, or Kafka.
Decoder
- Binlog (Binary Log): A set of files in MySQL that record all changes made to the database, commonly used for replication and point-in-time recovery.
- Parquet: A columnar storage format that is highly optimized for analytical queries, allowing engines to read only the necessary columns rather than entire rows.
- ETL (Extract, Transform, Load): The traditional process of moving data from operational databases into a centralized warehouse for analysis.
- OLTP (Online Transactional Processing): Databases designed for fast, frequent read/write operations of individual records.
Original article
Your application asks MySQL about now: this order, this customer, this cart. MySQL is very good at that.
Then the business asks about the past:
- Finance: revenue by month, for the last three years?
- Product: who churned after the price change?
- Support and compliance: what did this account look like on 3 March?
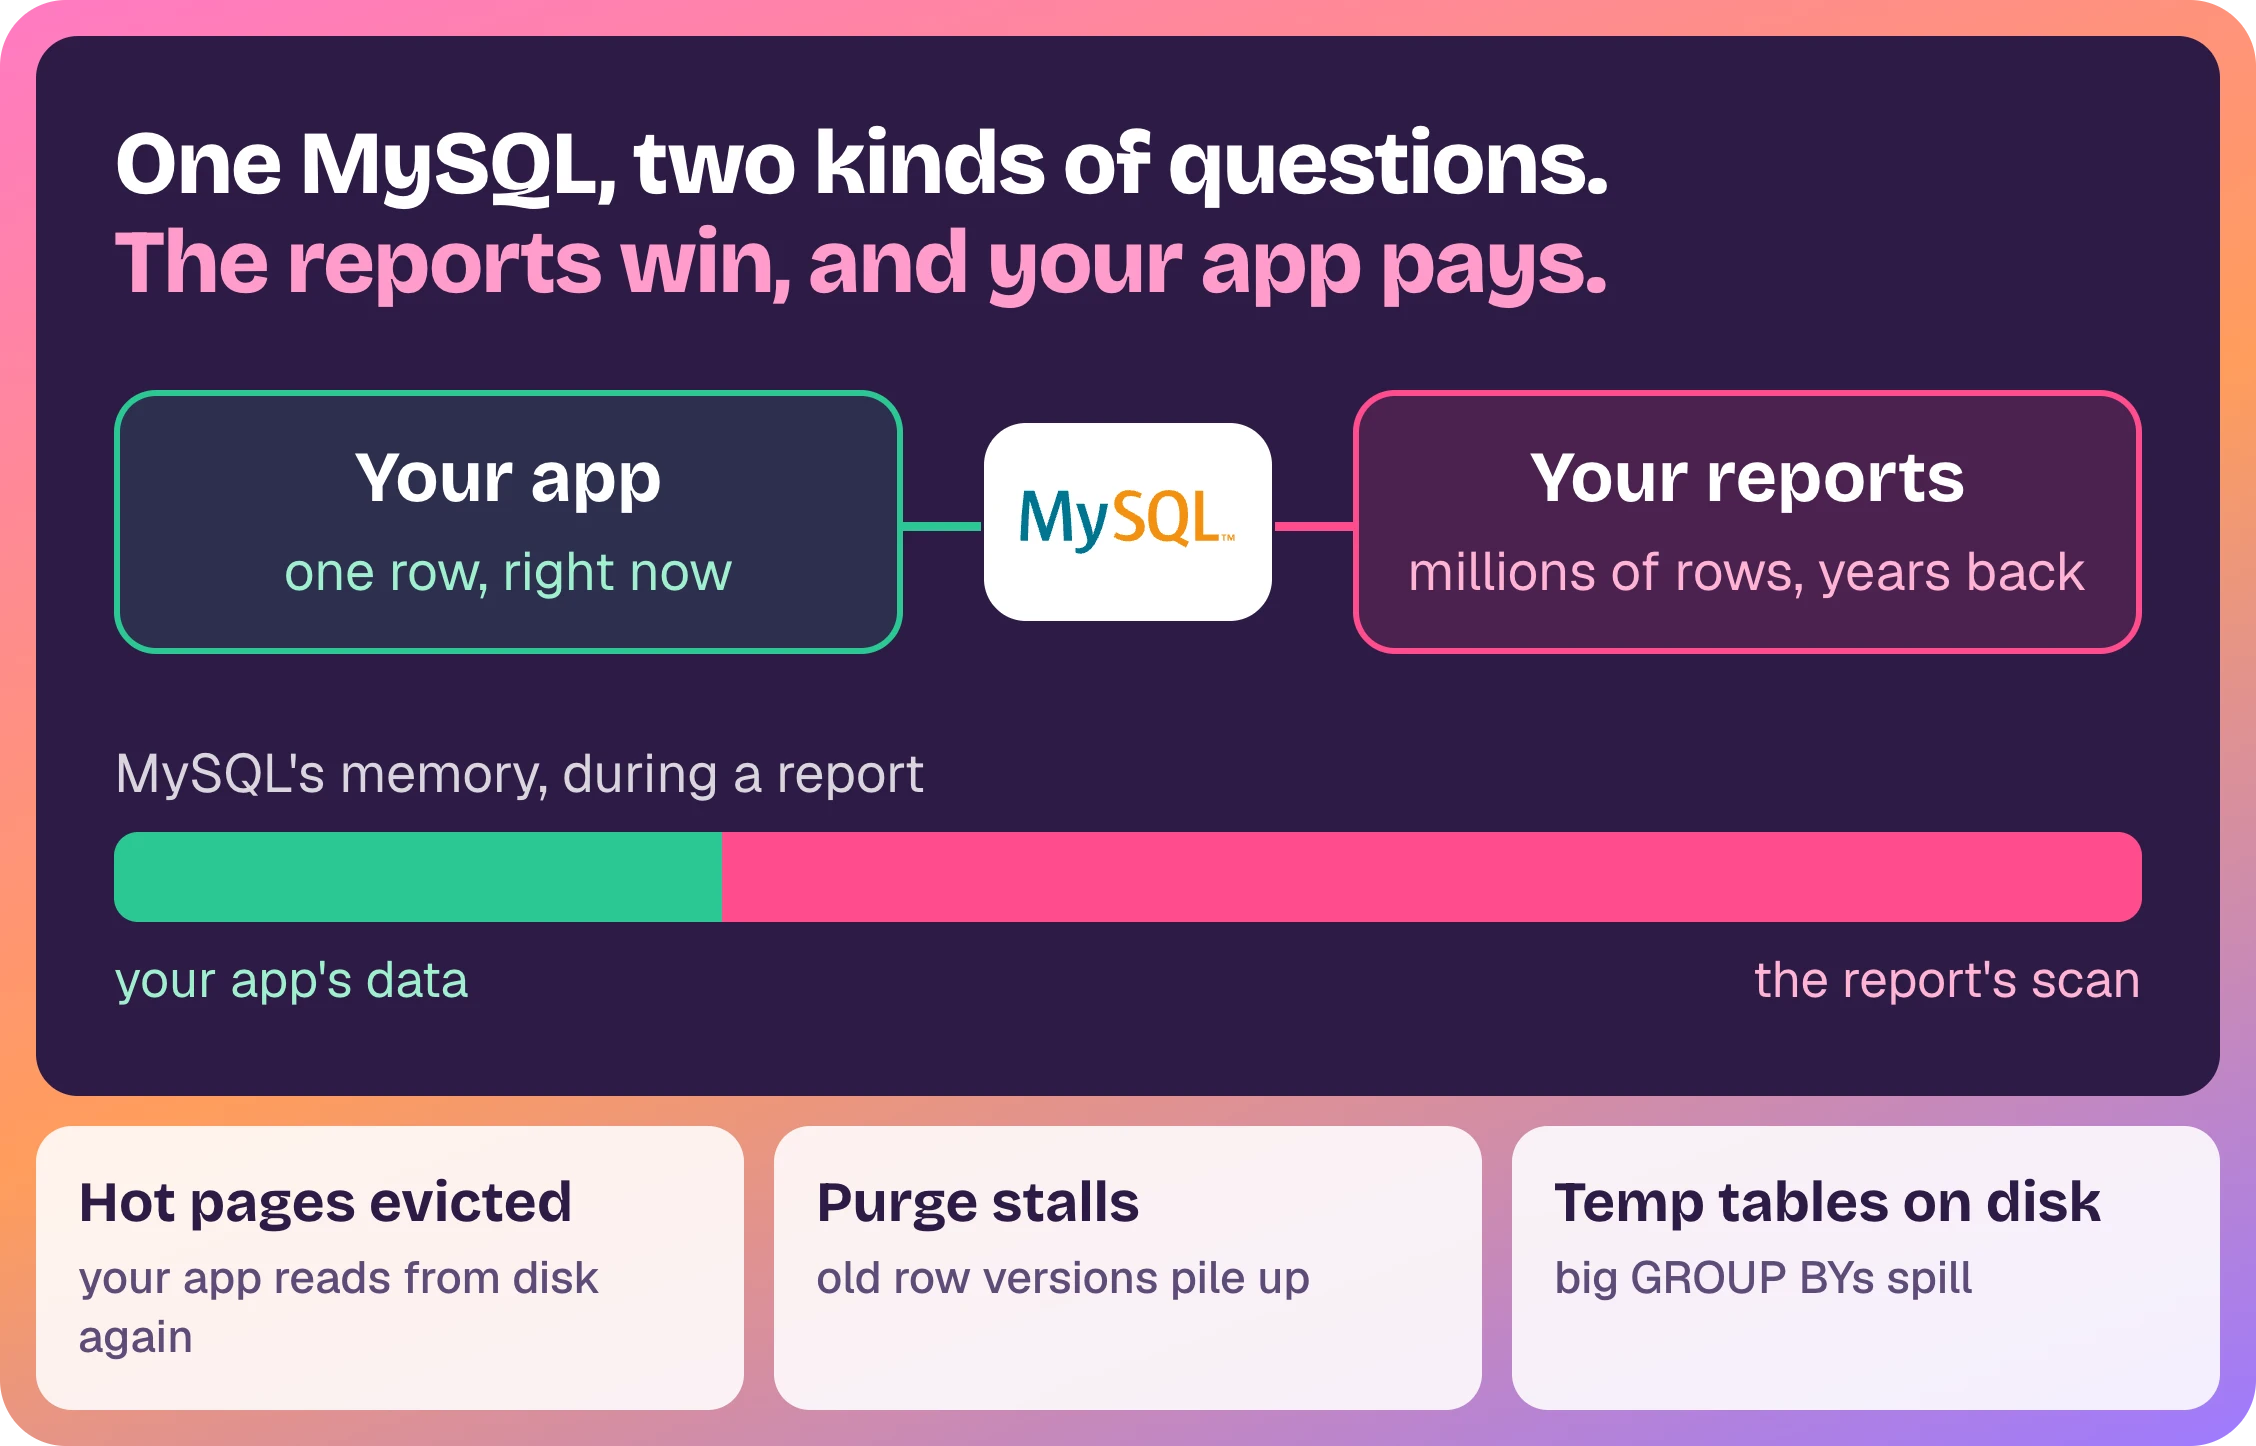
Those questions land on the same server as your application, and your primary pays for them. A full scan pushes your working set out of the buffer pool. A long read keeps old row versions alive and purge stalls behind it. A GROUP BY over millions of rows spills temp tables to disk. Row stores answer “now” fast. “Over time” is a different shape of question.
Give those queries a copy they can’t hurt. That is what we are introducing today.
What it is
DBTrail is an open-source analytical replica for MySQL. It keeps a copy of your tables made for reports, as Parquet files (an open format that stores a table column by column, so a report reads only the columns it needs) in a folder or an S3 bucket you own. It follows every change in your MySQL, updates the copy on the schedule you set, and you query it with DuckDB, a free SQL tool that runs on your laptop or a server.
How it works:
- The first copy reads all your tables (with mydumper). This is the one moment DBTrail reads your data directly.
- After that, only the binlog. DBTrail reads it from outside, the way a MySQL replica does. Nothing is installed in MySQL: no plugin, no agent on the database host, no triggers. RDS and Aurora work.
- On your schedule, the copy is updated by folding the changes into a new Parquet snapshot. As often as every 5 minutes, or once a day. Your database is not read again for it, unless a table changes shape (see the limits below).
- You query it with DuckDB. DBTrail gives you a
views.sqlfile with one view per table, so you writeFROM state_shop_ordersand get the table as of the latest snapshot.
No ETL. No scripts or jobs to write to move data out of MySQL. No warehouse to run. One Docker Compose stack, and a folder or a bucket.
A lakehouse without the pipeline
“Lakehouse” sounds like data-engineering jargon, but for a DBA it is easy to picture: your tables as open files in cheap object storage, plus a thin layer that makes those files behave like tables, queried by whatever engine you bring. Every part of your OLTP database is still there. It just stopped living in one process: .ibd files become Parquet in a bucket, mysqld becomes DuckDB, Athena or Spark.
The usual way to build one out of MySQL has three to five moving parts: a CDC tool (Debezium, Airbyte), often a stream (Kafka, Kinesis), a table format (Iceberg, Delta), a catalog (Glue, Nessie), an engine cluster. Some builds skip the stream or the catalog, but it is still a pipeline somebody owns.
DBTrail has one: your MySQL, with nothing installed → DBTrail → plain Parquet in your bucket → any reader. What it gives up is listed at the end of this post, said in the same voice as the strengths.
Querying it
Four steps from nothing to a query:
- Install. You need Docker with Compose. One command starts DBTrail, its web page, and the small MySQL it keeps its own index in.
- Connect your MySQL. Create your login in the page the installer opens and add your server. The page shows the SQL that creates DBTrail’s user.
- Take the first copy and pick a schedule. On Snapshots, press Read database now. Then in Settings, pick how often and press Turn on. Left as it comes, it runs once a day.
- Query it. On Snapshots, press Download, then Download the data. Unpack it and run DuckDB inside the folder:
$ duckdb -init views.sql
-- Loading resources from views.sql
D SELECT c.tier, count(*) AS orders, round(sum(o.total), 2) AS revenue
  FROM state_demo_orders o
  JOIN state_demo_customers c ON c.id = o.customer_id
  GROUP BY c.tier ORDER BY revenue DESC;
┌──────────┬────────┬───────────────┐
│   tier   │ orders │    revenue    │
│ varchar  │ int64  │ decimal(38,2) │
├──────────┼────────┼───────────────┤
│ platinum │ 539848 │   59426197.40 │
│ gold     │ 539752 │   59353658.54 │
│ silver   │ 539056 │   59295443.48 │
│ bronze   │ 538385 │   59242795.95 │
└──────────┴────────┴───────────────┘
One rule worth knowing early: open the copy through views.sql. Another engine reading the Parquet files directly sees each table as of its last full write and can miss the changes stored beside it.
The numbers, and how we got them
We did not want to publish numbers without the method, so here is both.
The setup. One source: RDS MySQL 8.4 with a TPC-C dataset, 73 million rows, about 10 GB, under a sysbench-tpcc load of 180 transactions per second. Five copies attached to it, one at a time, in 30 to 60 minute windows, measured 18 to 20 September 2026: an RDS read replica, DBTrail 0.84 (refreshing every 5 minutes for this test), ClickHouse fed by Airbyte CDC every 5 minutes, MyDuck Server (binlog into DuckDB), and Redshift zero-ETL. Every default kept. Every manual fix counted as “hands”.
How fresh is it? In a separate measurement under about 340 transactions per second, commit to visible in DuckDB took 2.7 to 13.2 minutes, median 5.9, with a 5-minute schedule. Minutes, not seconds, and not yet repeatable, which is why it is also in the limits below.
Other engines read the same bytes
Because the copy is plain Parquet, it is not locked to DuckDB. We ran the same top-5 query over 55.6 million rows from one snapshot file in DuckDB on a laptop, in ClickHouse with s3() and zero configuration (3.0 s), and in Athena after a Glue crawler (2.2 s). Same answer from all three, no conversion. The caveat from before applies: an outside reader has to apply the change files next to the table, which the DuckDB views do for you.
What else comes from the same capture
The binlog DBTrail reads for the copy also carries every row change, with the row before and after. Starting the day you install it, the same install gives you:
- Row history and undo. See any row before and after a change, and get the SQL that puts it back: the
UPDATEwithout aWHERE, theDELETEthat cascaded. DBTrail generates the SQL; it never runs it for you. - Tables as they were at a moment. Rebuild whole tables as of a past time.
- A row as it was, from your own MySQL client. An optional time-travel port speaks the MySQL protocol, for looking at rows, not for running reports:
mysql> SELECT * FROM speakers WHERE id = 67 AS OF '2026-08-19 09:12:00';- Ask in plain English. Connect Claude and ask about your changes in words. Every tool is read-only.
Where it stops
A copy you can trust is one whose edges you know.
The scheduled copy is for MySQL and Percona Server 8.0 and 8.4, including RDS and Aurora.
Try it
DBTrail is Apache 2.0. All of it: capture, index, console, recovery, the Parquet you open in DuckDB, and the MCP server that lets an assistant drive it.
- Start here: Quick Start
- What it is, in one page: dbtrail.com/docs
- Source: github.com/dbtrail/dbtrail
Fresh dev news, AI-digested daily. Never miss a trend at devoured.fyi