Keenable SELECT showcase (Tool)
Keenable SELECT allows AI agents to research the live web by executing read-only SQL queries that integrate search, semantic filtering, and data extraction.
Deep dive
- Operates as an MCP server with one primary tool:
select. - Uses DuckDB for the final SQL execution after running custom web and semantic operators.
WEB_SEARCHmerges results from multiple queries simultaneously to reduce search latency.SEM_EXTRACTandSEM_EXTRACT_ALLperform LLM-based data extraction on a per-row basis.SEM_MATCHacts as a meaning-based filter equivalent to a SQL WHERE clause.- Automates reporting via a
generate_html_reporttool that renders data into shareable documents.
Decoder
- MCP (Model Context Protocol): An open standard that enables AI models to connect to local and remote data sources via a consistent tool interface.
- DuckDB: An in-process SQL OLAP database management system designed for fast analytical queries.
- Agentic framework: A set of tools and methodologies designed to allow LLMs to perform multi-step tasks by executing tools and reflecting on the results.
Original article
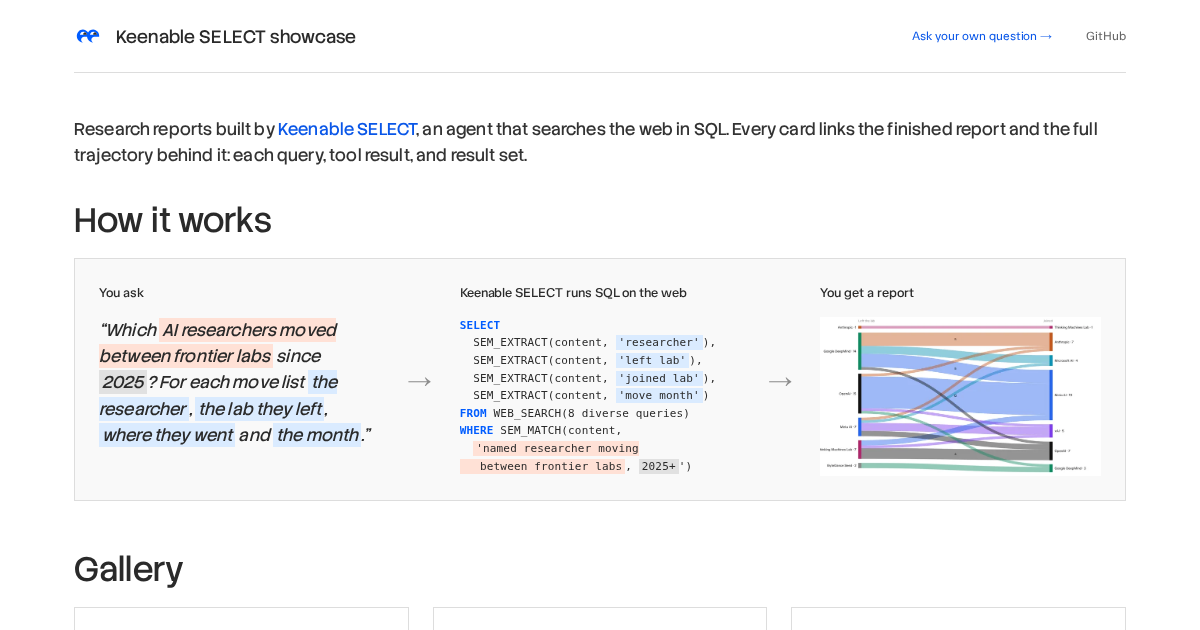
Research reports built by Keenable SELECT, an agent that searches the web in SQL. Every card links the finished report and the full trajectory behind it: each query, tool result, and result set.
How it works
You ask: “Which AI researchers moved between frontier labs since 2025? For each move list the researcher, the lab they left, where they went and the month.”
Keenable SELECT runs SQL on the web:
SELECT
  SEM_EXTRACT(content, 'researcher'),
  SEM_EXTRACT(content, 'left lab'),
  SEM_EXTRACT(content, 'joined lab'),
  SEM_EXTRACT(content, 'move month')
FROM WEB_SEARCH(8 diverse queries)
WHERE SEM_MATCH(content,
  'named researcher moving
   between frontier labs, 2025+')
You get a report.
Gallery
- Twenty Years of YC Startup-Name Morphology
- A Living History of Search Engines (1982–2026)
- America’s Gigawatt AI Data-Center Buildout
- Atlas of Documented Zoo Animal Escapes
- Best New Casual Southeast Asian Restaurants in the Bay Area
- Bollywood Songs Reported as Copied or Inspired
- Death by GPS: Documented Water, Desert & Cliff Incidents
- Frontier AI Researcher Moves Since 2025
- Great Bird Migrations of the World
- India’s Famous Mango Origins Map
- Major Open & Open-Weight LLM Releases — 2026 Timeline
- Marvel Screen Continuities, 2005–2026 — Light Edition
- Mechanical Keyboard Releases — 10-Year Timeline
- Nearest Zoo Voronoi Atlas — United States
- Orbital Launch Atlas, 1957–2026
- Popular Open-Source AI Agents & Agentic Frameworks
- Seattle & Bellevue Coffee Enthusiast Tour
- The AI Lab Founder Family Tree
- The Great-Chef Kitchen Lineage
- U.S. Specialty Coffee Roaster Atlas
- What Goes in Common EDC Packs?
- Australia’s Big Things — Map and Route
- Bay Area First-Date Playbook
- Braintrust (braintrust.dev) — Public-Source Org Chart
The system behind the reports
Keenable SELECT is an MCP server with one main tool: select. The tool runs one read-only DuckDB SELECT statement on live web data. The server runs the web and semantic operators outside DuckDB, puts their output back into the row set, and then runs the final SQL in DuckDB.
A traditional web search gives an agent ten links. The agent must then read each page and build the answer from expensive tokens. SELECT moves this work into the query. One call can search more than 1,000 pages, filter them with an exact WHERE clause at no LLM cost, extract fields with one small LLM call per row, and group the rows.
MCP tools
selecttakes DuckDBSELECTqueries and returns the rows. The server saves every query result as a result set with an id, and a later query can read from that id.generate_html_reporttakes a brief and result set ids. A report model on the server writes an HTML report from the rows and returns a shareable link.
Semantic operators
The operators live inside normal SQL. The server finds them in the parsed statement, runs them, and replaces them with plain columns. Exact SQL filters run first, so only the surviving rows go to the LLM operators.
| Operator | What it does |
|---|---|
WEB_SEARCH('q1', 'q2', ...) |
Searches all queries at the same time, merges ranked results, and removes repeated URLs. |
WEB_FETCH('https://a.com', ...) |
Gets the given URLs as Markdown, one row per page. |
SEM_EXTRACT(column, 'field description') |
One LLM call per row. It returns one field, or null when the text does not give the value. |
SEM_EXTRACT_ALL(column, 'what one value is') |
Like SEM_EXTRACT, but returns all matching values in a list. |
SEM_MATCH(column, 'predicate') |
An LLM test per row. Use it as a meaning-based WHERE filter. |
SEM_SCORE(column, 'query') |
A low-cost embedding score per row. Use ORDER BY ... DESC LIMIT k. |
SEM_NORM(column) |
Gives the same key to values with the same meaning. Use it in GROUP BY. |
WEB_SEARCH and WEB_FETCH can also run per row. Their arguments can use row columns, for example WEB_SEARCH(name || ' founding year').
Main agent
Every report in this gallery comes from two agents: a research agent that uses the MCP server to gather the data, and a report agent that runs inside generate_html_report on the server and writes the page.
The research agent is a plain tool loop: an LLM with the select tool. It writes and runs its own queries until it can answer, and streams its tool calls, results, and answer as events. A follow-up question continues the conversation on top of the stored transcript. Every run in this showcase asks for an HTML report, so the agent ends each answer with the report link.
Report agent
A second agent writes each report on the server. It gets the brief, the rows of the result sets, and an authoring guide. It builds the page in a sandboxed Python session that holds the result sets as dataframes, so the data reaches the page without the model retyping it. After each publish, the server renders the draft and returns screenshots and the page's JavaScript error count; the agent fixes the document and publishes again, under a fixed budget. Only the final draft stays live, published as a link.
Fresh dev news, AI-digested daily. Never miss a trend at devoured.fyi