OpenAI's GPT-6 Astra on ARC-AGI-3
GPT-6 Astra achieved a 99.9% success rate on the ARC-AGI-3 benchmark, displaying an ability to invent custom shorthand to model environment states.
Deep dive
- Benchmark Performance: Scored 62.7% on the standard harness and 99.9% on the provider-adapted harness.
- World Modeling: The model generated algebraic notation to track object movement, game rules, and plan multi-step sequences.
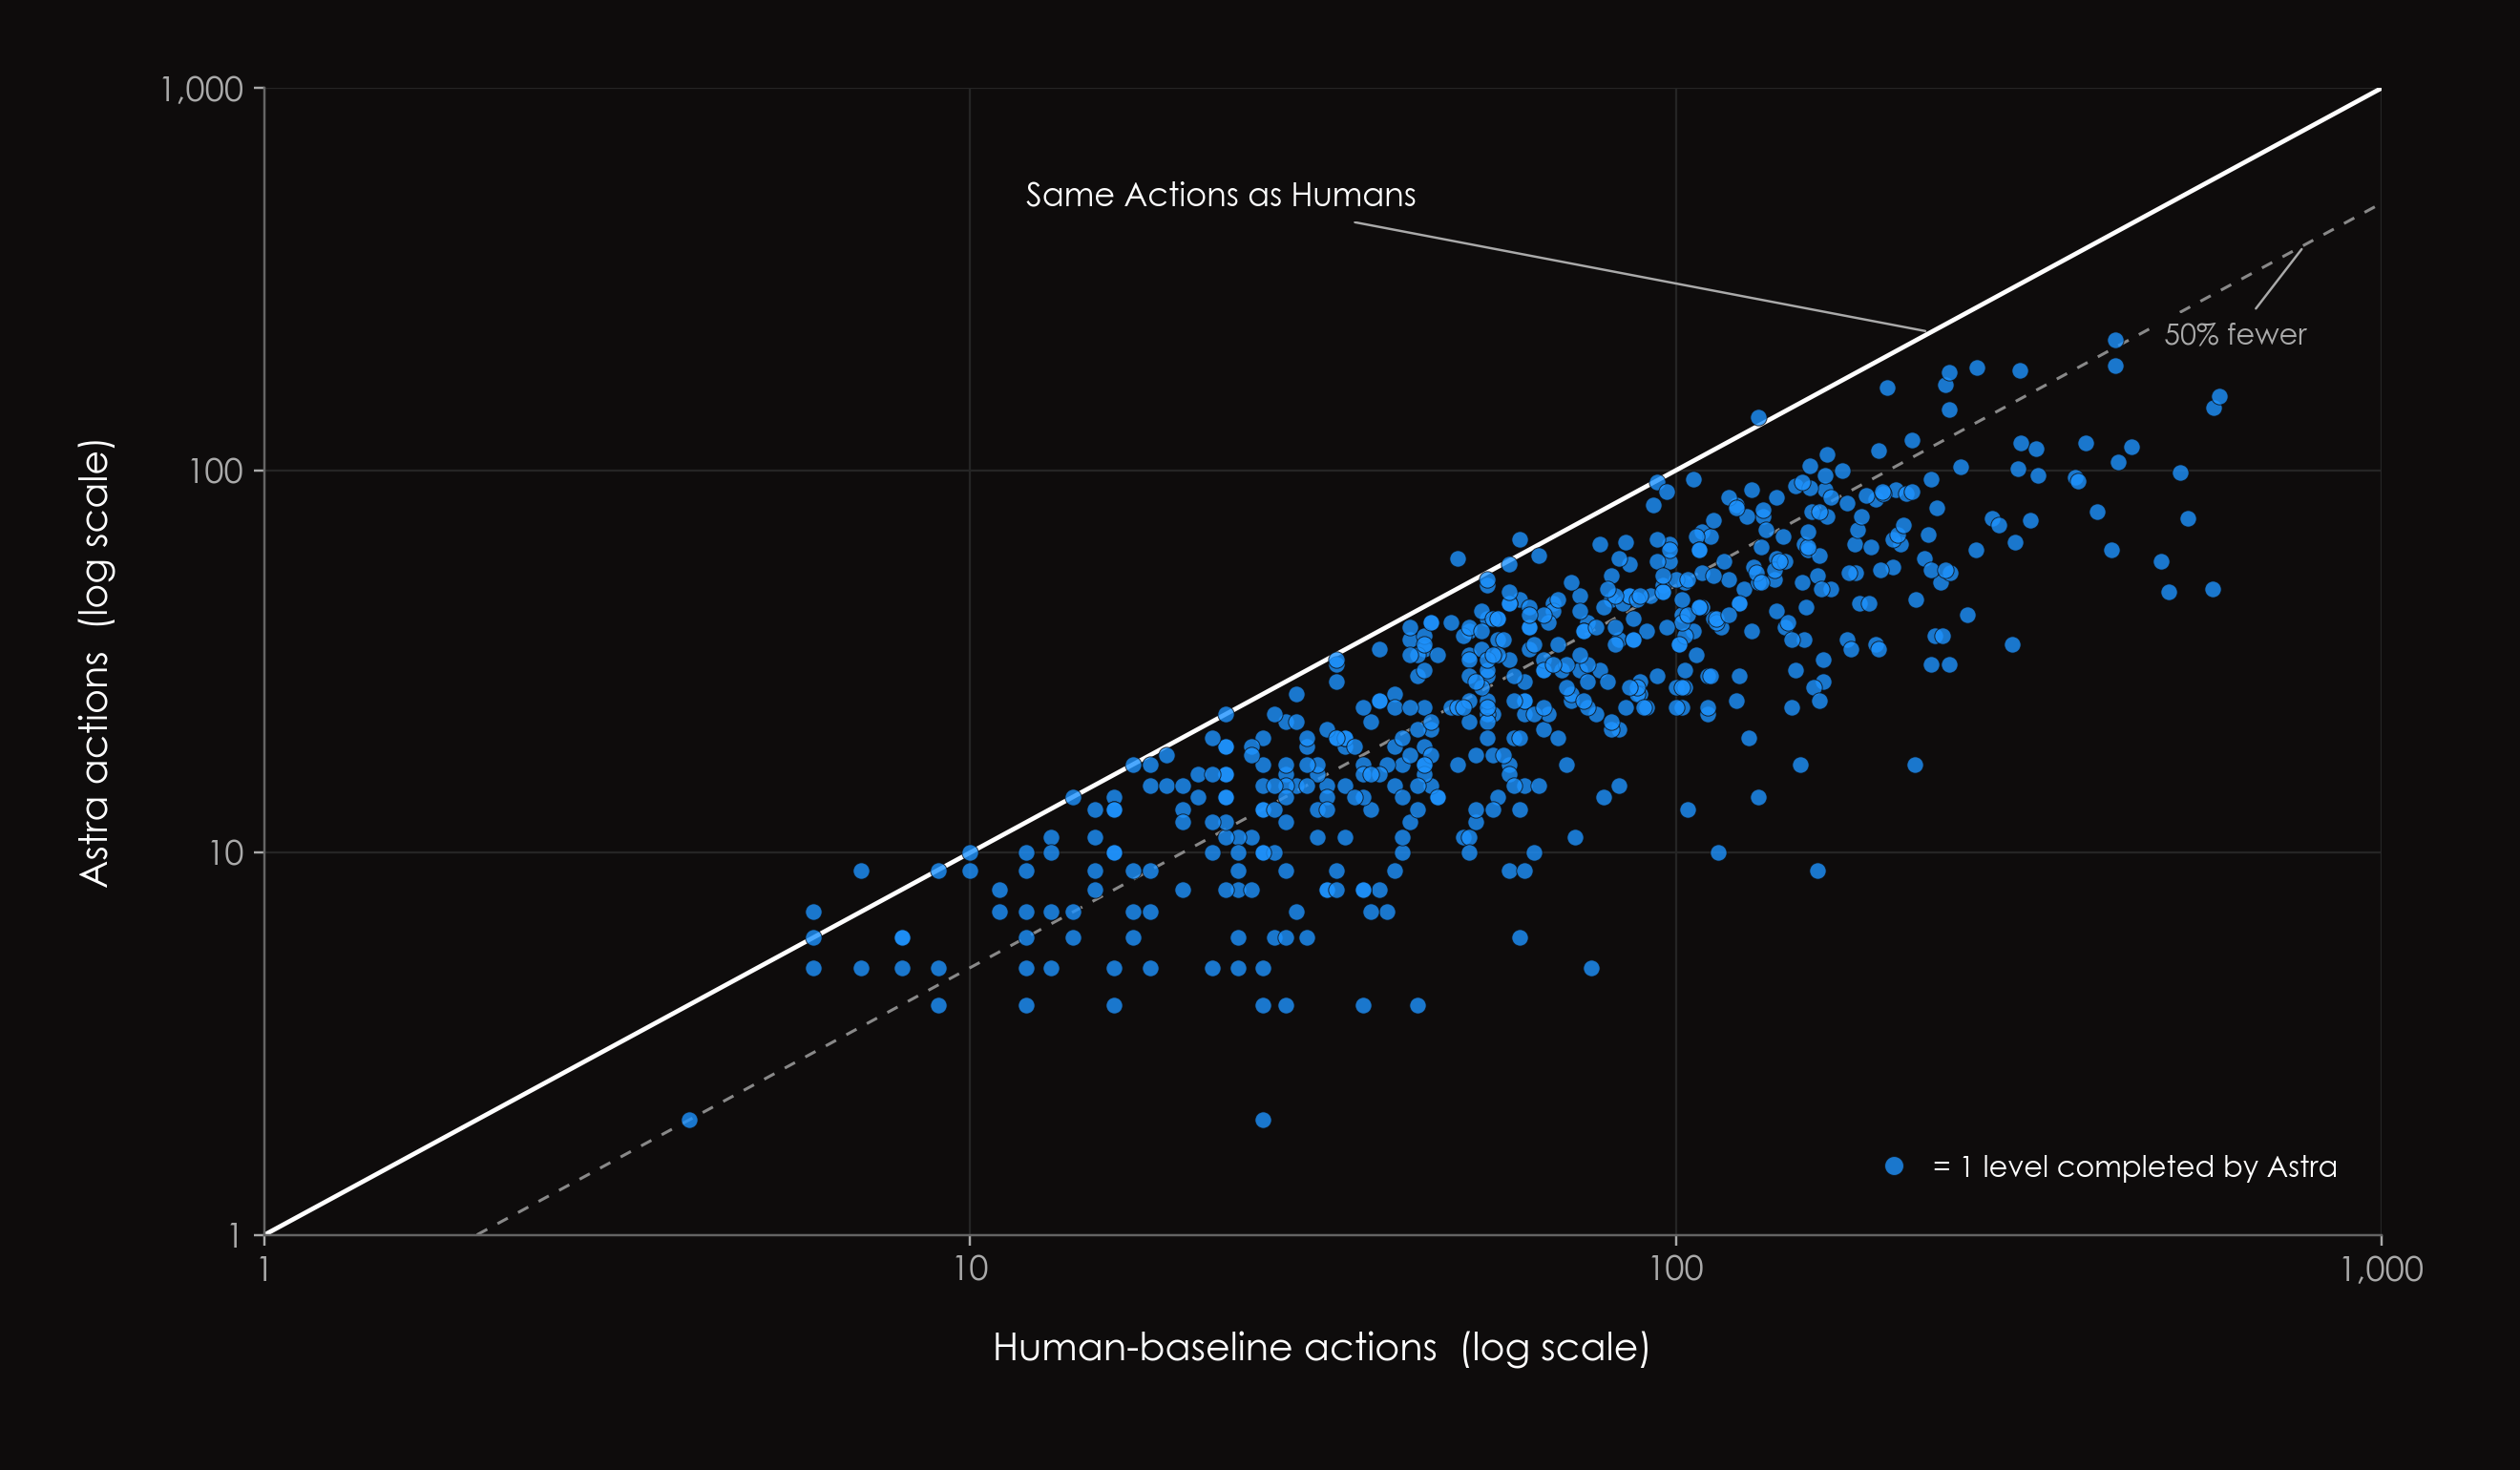
- Action Efficiency: Surpassed human performance by requiring fewer interactions to solve puzzles.
- Tool Creation: When provided a sandbox, the model autonomously generated Python libraries to solve specific levels.
Decoder
- ARC-AGI: A benchmark created by François Chollet to measure a system's ability to learn new skills in novel, abstract environments.
- Symbolic world model: A mental (or digital) representation that uses logic and rules rather than just statistical pattern matching.
Original article
OpenAI's GPT-6 Astra on ARC-AGI-3
Summary
- GPT-6 Astra scores 62.7% for $26K on ARC-AGI-3 Semi-Private with our Standard harness, and 99.9% for $19K with a Provider Adapter harness.
- GPT-6 Astra surpasses the human baseline in action efficiency on ARC-AGI-3. It used fewer actions than the median tested human on 96% of levels.
- A key behavior observed in GPT-6 Astra was its ability to turn unfamiliar environments into compact symbolic world models. It represented game mechanics as logical rules and developed its own domain-specific language shorthand to track state and plan actions.
ARC-AGI-3
ARC-AGI-3 is a benchmark for studying agentic intelligence through novel, abstract, turn-based environments. Agents must explore, infer goals, and build internal models of environments to effectively plan actions without explicit instructions.
These environments only contain core knowledge priors and are difficulty-calibrated through controlled testing with human participants. Humans can solve 100% of the environments.
The goal of the ARC-AGI series is to measure the “residual gap” between current artificial intelligence and AGI. We define AGI as a system’s ability to acquire any skill a human can, as efficiently as a human can.
ARC-AGI-3 is the third generation of the ARC-AGI benchmark series. It tests agentic capabilities beyond ARC-AGI-1 and ARC-AGI-2. Each generation expands on the one before it - as frontier AI capabilities advance, our benchmarks must advance with them.
ARC-AGI-3 tests four components of agentic intelligence:
- Exploration: In real-world environments, information is rarely provided passively. Agents must actively obtain it by interacting with their surroundings.
- Modeling: Agents must turn raw observations into a generalizable model that can predict future states and outcomes.
- Goal-setting: Agents must identify target future states with only sparse rewards.
- Planning and execution: Agents must map a path from their current state to a goal, course correcting as new information appears.
Astra Results
With our Standard harness, OpenAI’s Astra (max) scores 62.7% on ARC-AGI-3 Semi-Private for $26K. With the Provider Adapter harness, Astra (high) scores 99.9% for $19K. Both are state-of-the-art scores.
| Reasoning effort | Standard harness | Provider Adapter harness |
|---|---|---|
| max | 62.7%, $26,098 | 98.6%, $17,332 |
| xhigh | 59.3%, $37,317 | 98.4%, $18,147 |
| high | 54.8%, $40,705 | 99.9%, $18,817 |
| medium | 38.6%, $48,090 | 98.4%, $19,285 |
| low | 17.5%, $38,166 | 98.0%, $21,298 |
| none | 35.2%, $49,791 | 96.7%, $23,457 |
For a cost comparison, during our controlled testing, human participants were paid $115 per 90-minute session, plus $5 per game completed. Participants attempted approximately nine games per session, roughly $12.78 per attempted game before bonuses.
Most of this fee pays for the participant’s time and willingness to take the test, rather than the energy their brain uses. If we look at only the brain’s energy, and price it as electricity, the estimate drops to about 0.6 cents per session, or 0.067 cents per game attempted.
Analysis
Beyond the scores, Astra’s replays show how it turns unfamiliar game mechanics into useful working models. Three findings stood out: the compact algebraic notation it develops, its action efficiency compared with humans, and the custom tools it builds.
Custom Algebraic Notation
When playing ARC-AGI-3, Astra chooses which strategy notes it would like to carry forward. It tracked objects, coordinates, rules, and unfinished plans, while also using a custom domain-specific language notation it generated for the environments.
Astra’s notes stood out for their precision and information density. It distilled the scene into a compact code-like symbolic model: where objects were, how they interacted, and exactly which actions needed to happen in what order. This is an on-the-fly algebraic shorthand rather than a fully fledged programming language. For example:
- Game state:
L8: hub q2 (8↓). Lengths: 14=1…records the level, a local rotation index, and mechanism lengths. - Multi-step plans:
extend8 to3; retract10 to2; shorten8 to1records an ordered sequence of changes to the color-8 and color-10 mechanisms. - Controls and coordinates:
9−=(39,4), rotate=(49,18), 14+=(59,11)maps operations to the coordinates of the controls that perform them. - Time and position:
Turn 5: P=(24,20), empty, facing westcombines a turn counter with the player’s location, carrying state, and orientation.
Action Efficiency Compared to Humans
Before launching ARC-AGI-3, we tested approximately 500 members of the general public to establish a human baseline for action efficiency. For each level, we defined the “human baseline” using the median action count among players who completed it.
In the Provider Adapter harness, Astra (max) used fewer actions than the human baseline on 96.0% of levels and used 51.7% fewer actions per level on average. This is a material milestone. This means by ARC-AGI-3’s measure of action efficiency, Astra matched and surpassed human parity.
Astra’s results show that it needed fewer interactions than the human baseline to execute a solution.
Custom Tools in Agent Harness
We also evaluated Astra in the PRO-LONG harness, an early ARC-AGI-3 red-teaming partner. In this advanced setup, Astra had access to a sandbox where it could execute custom code. We observed Astra create a custom set of tools for each game: board parsers, game-state models, search algorithms, planners, and persistent notes. For more involved runs, Astra even produced small, game-specific software libraries.
Two Harnesses, Two Questions
Our Standard harness for ARC-AGI-3 asks how models compare under the same minimal, provider-neutral interface. Alternatively, the Provider Adapter harness asks how well a model performs when it can use the context-management features its provider designed for it.
With the Provider Adapter harness, Astra's best observed score on ARC-AGI-3 Semi-Private increased from 62.7% to 99.9%. Looking across Public and Semi-Private and all reasoning levels, Provider Adapter runs were approximately 3.66x faster by aggregate recorded elapsed time and used 49% fewer total tokens across the 167 game-reasoning pairs both harnesses solved.
ARC-AGI Series
ARC-AGI-3 continues to be a useful playground for researchers and agents to explore unfamiliar environments, discover rules, and learn through interaction. Astra’s results are also a major milestone worth celebrating. From our perspective, Astra represents a noticeable step-function change in frontier model capabilities.
While we believe Astra represents meaningful progress towards generalization, we are not claiming that it is AGI. The ARC-AGI benchmark series is designed to evolve in tandem with frontier AI. Astra’s progress helps clarify which AI capabilities are out of reach and which questions remain open.
Thank you to François Chollet, Mike Knoop, Matt Mazur, Ethan Bond, and Derek Smith for early review of this post.
- Assuming 20 W of brain metabolic power and an electricity price of $0.20/kWh: 0.020 kW × 1.5 hours = 0.030 kWh, worth $0.006 per session, or $0.006 ÷ 9 ≈ $0.00067 per attempted game.
- See the ARC-AGI-3 human testing paper.
- No evidence of trying to break out of the sandbox was observed.
Fresh dev news, AI-digested daily. Never miss a trend at devoured.fyi