DEVOURED
Bad benchmarks and evals: Senior SWE-Bench, napkin math, and winter tires
Benchmarks are often more misleading than helpful; a critical look at SWE-Bench, napkin math, and tire performance reveals that expertise matters more than summary scores.
What: Author Dan Luu provides a deep-dive teardown of three types of benchmarks: system performance estimates, AI coding model evals, and seasonal tire metrics. He highlights how arbitrary thresholding and lack of representativeness make most headline scores 'meaningless' for actual decision-making.
Why it matters: This illustrates a recurring failure mode in engineering: using 'vanity metrics'—like a single pass/fail benchmark score—instead of understanding the underlying system mechanisms or deriving performance from first principles.
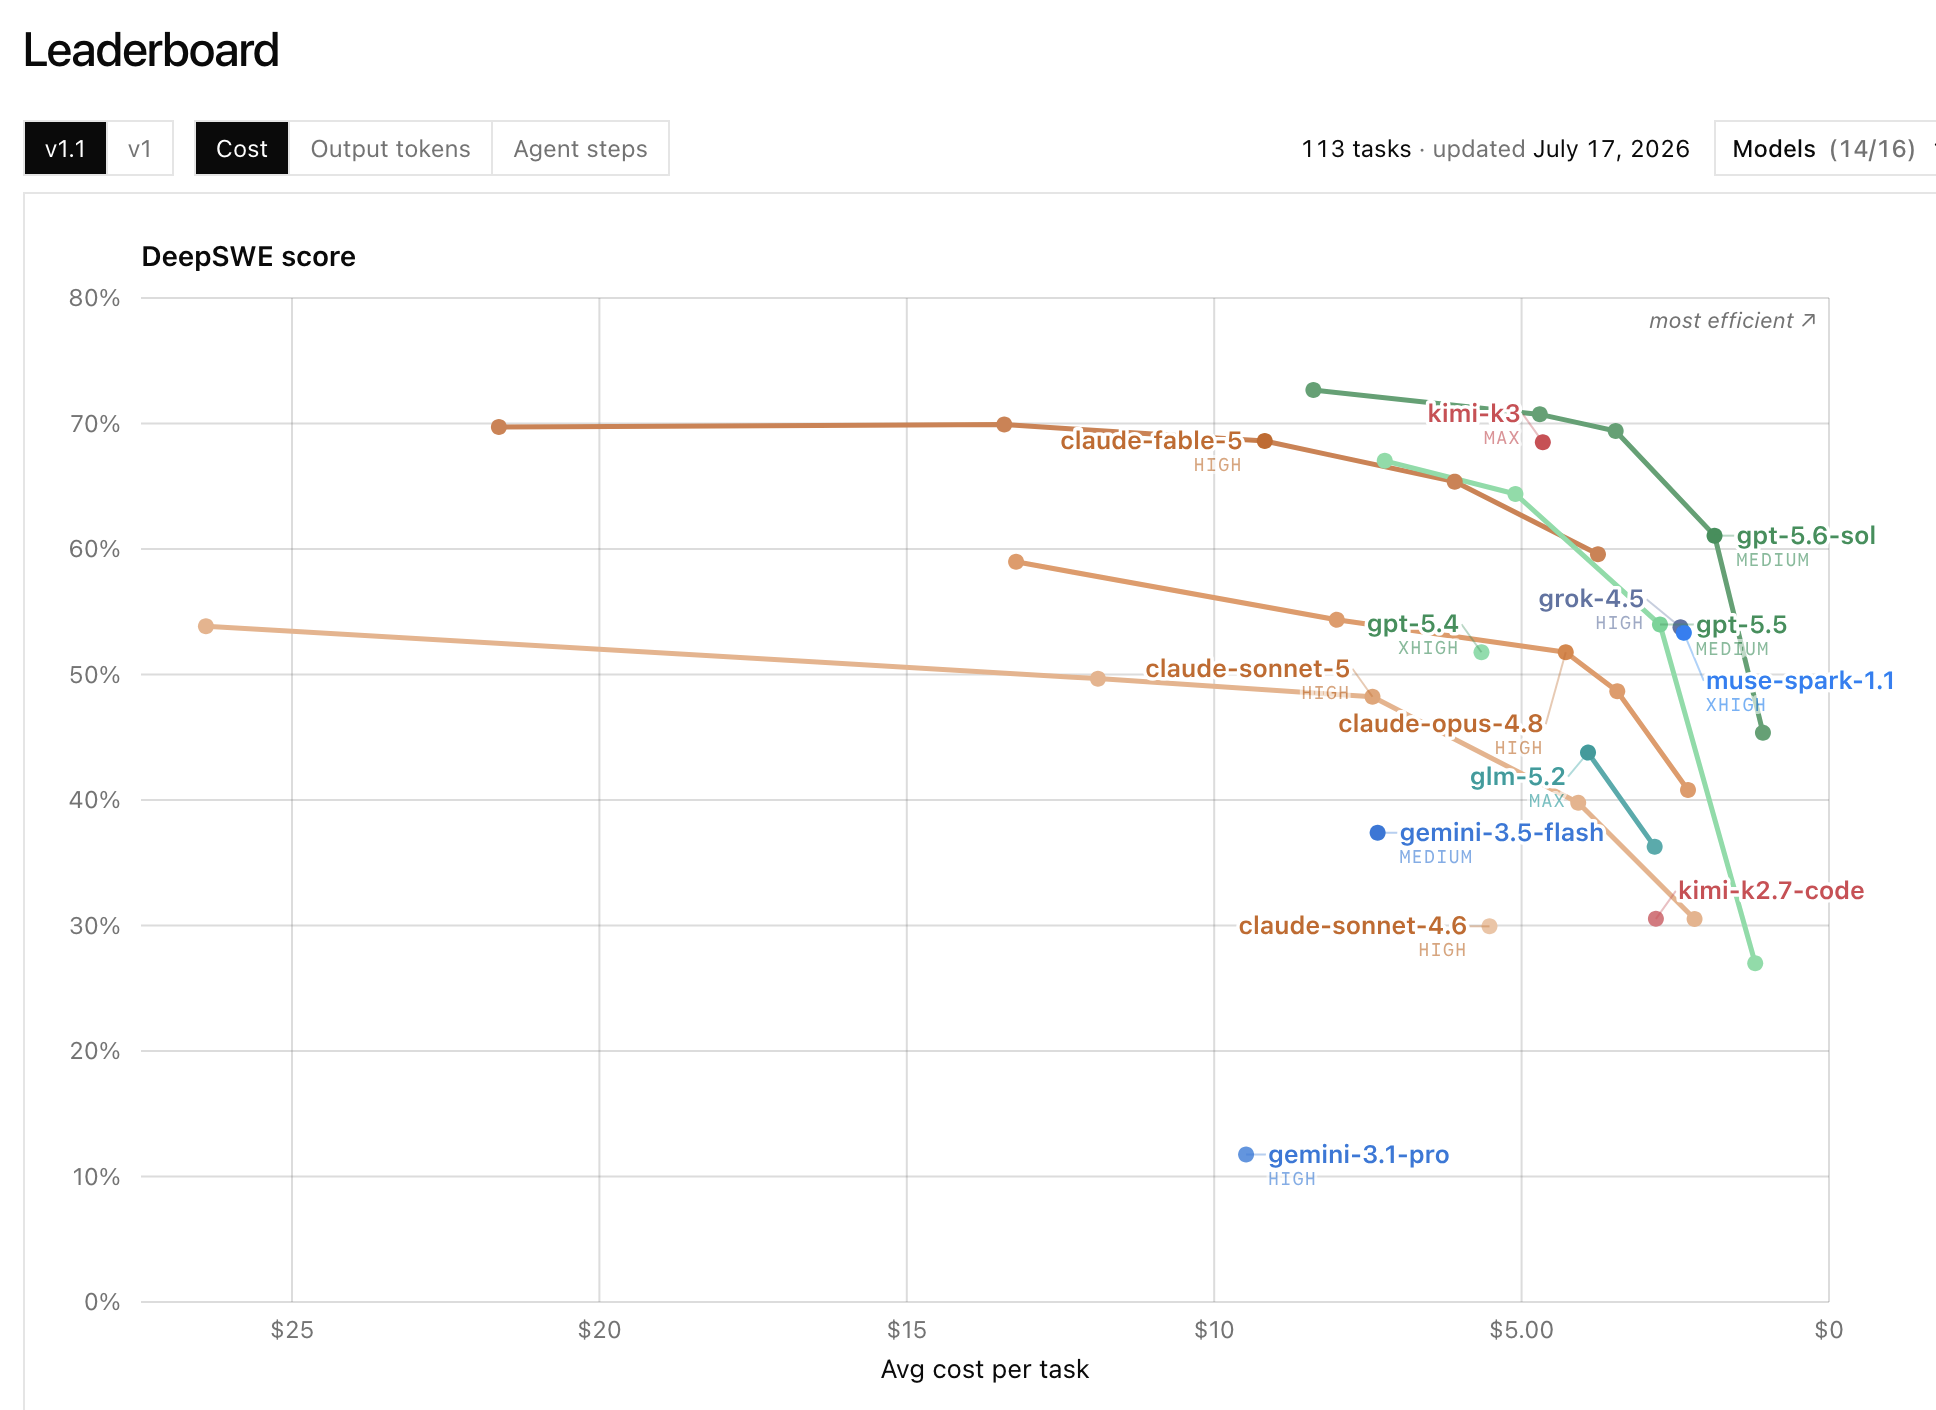
Takeaway: If you are using SWE-Bench scores to choose between models, ignore the aggregate ranking and look specifically at the task-level methodology to see if the evaluation correlates with your actual development workflows.
Deep dive
- Napkin Math Issues: Performance estimates for memory access often conflate parallelism with latency, leading to flawed baseline assumptions for interview prep.
- Discontinuity in Scoring: Benchmarks like Senior SWE-Bench use arbitrary cutoffs (e.g., LOC limits) that create noise-driven 'pass/fail' results instead of continuous, useful feedback.
- Grading Variance: Re-running LLM-based grading on the same code solutions produces drastically different 'tastefulness' scores, indicating the grading system is as unreliable as the models themselves.
- Benchmark Noise: On many tasks, the performance difference between models is statistical noise, yet it is presented as a meaningful hierarchy.
- First Principles: Understanding the 'why' (e.g., bus timings, disk I/O prefetching) is more durable and useful than memorizing tables of metrics.
Decoder
- SWE-Bench: A benchmark for evaluating how well AI models can resolve software engineering issues in GitHub repositories.
- HIC (Head Injury Criterion): A measure of the likelihood of head injury arising from an impact, often used in automotive crash testing.
Original article
Full article content is not available for inline reading.
Explore all 47 articles in today's digest
Fresh dev news, AI-digested daily. Never miss a trend at devoured.fyi