Google released Gemini 3.8 Live and 3.8 Live Extended Thinking today
Google launched Gemini 3.8 Live and 3.8 Live Extended Thinking, speech-to-speech models enabling real-time, interruptible voice conversations.
Decoder
- Speech-to-speech (S2S): Models that process audio input and generate audio output directly, bypassing the need for separate transcription and text-to-speech layers.
- WebSocket: A communication protocol providing full-duplex, bidirectional communication channels over a single TCP connection, ideal for low-latency AI interactions.
Original article
Google released Gemini 3.8 Live and 3.8 Live Extended Thinking today - two new speech-to-speech models that are a similar shape to OpenAI's GPT-Live family.
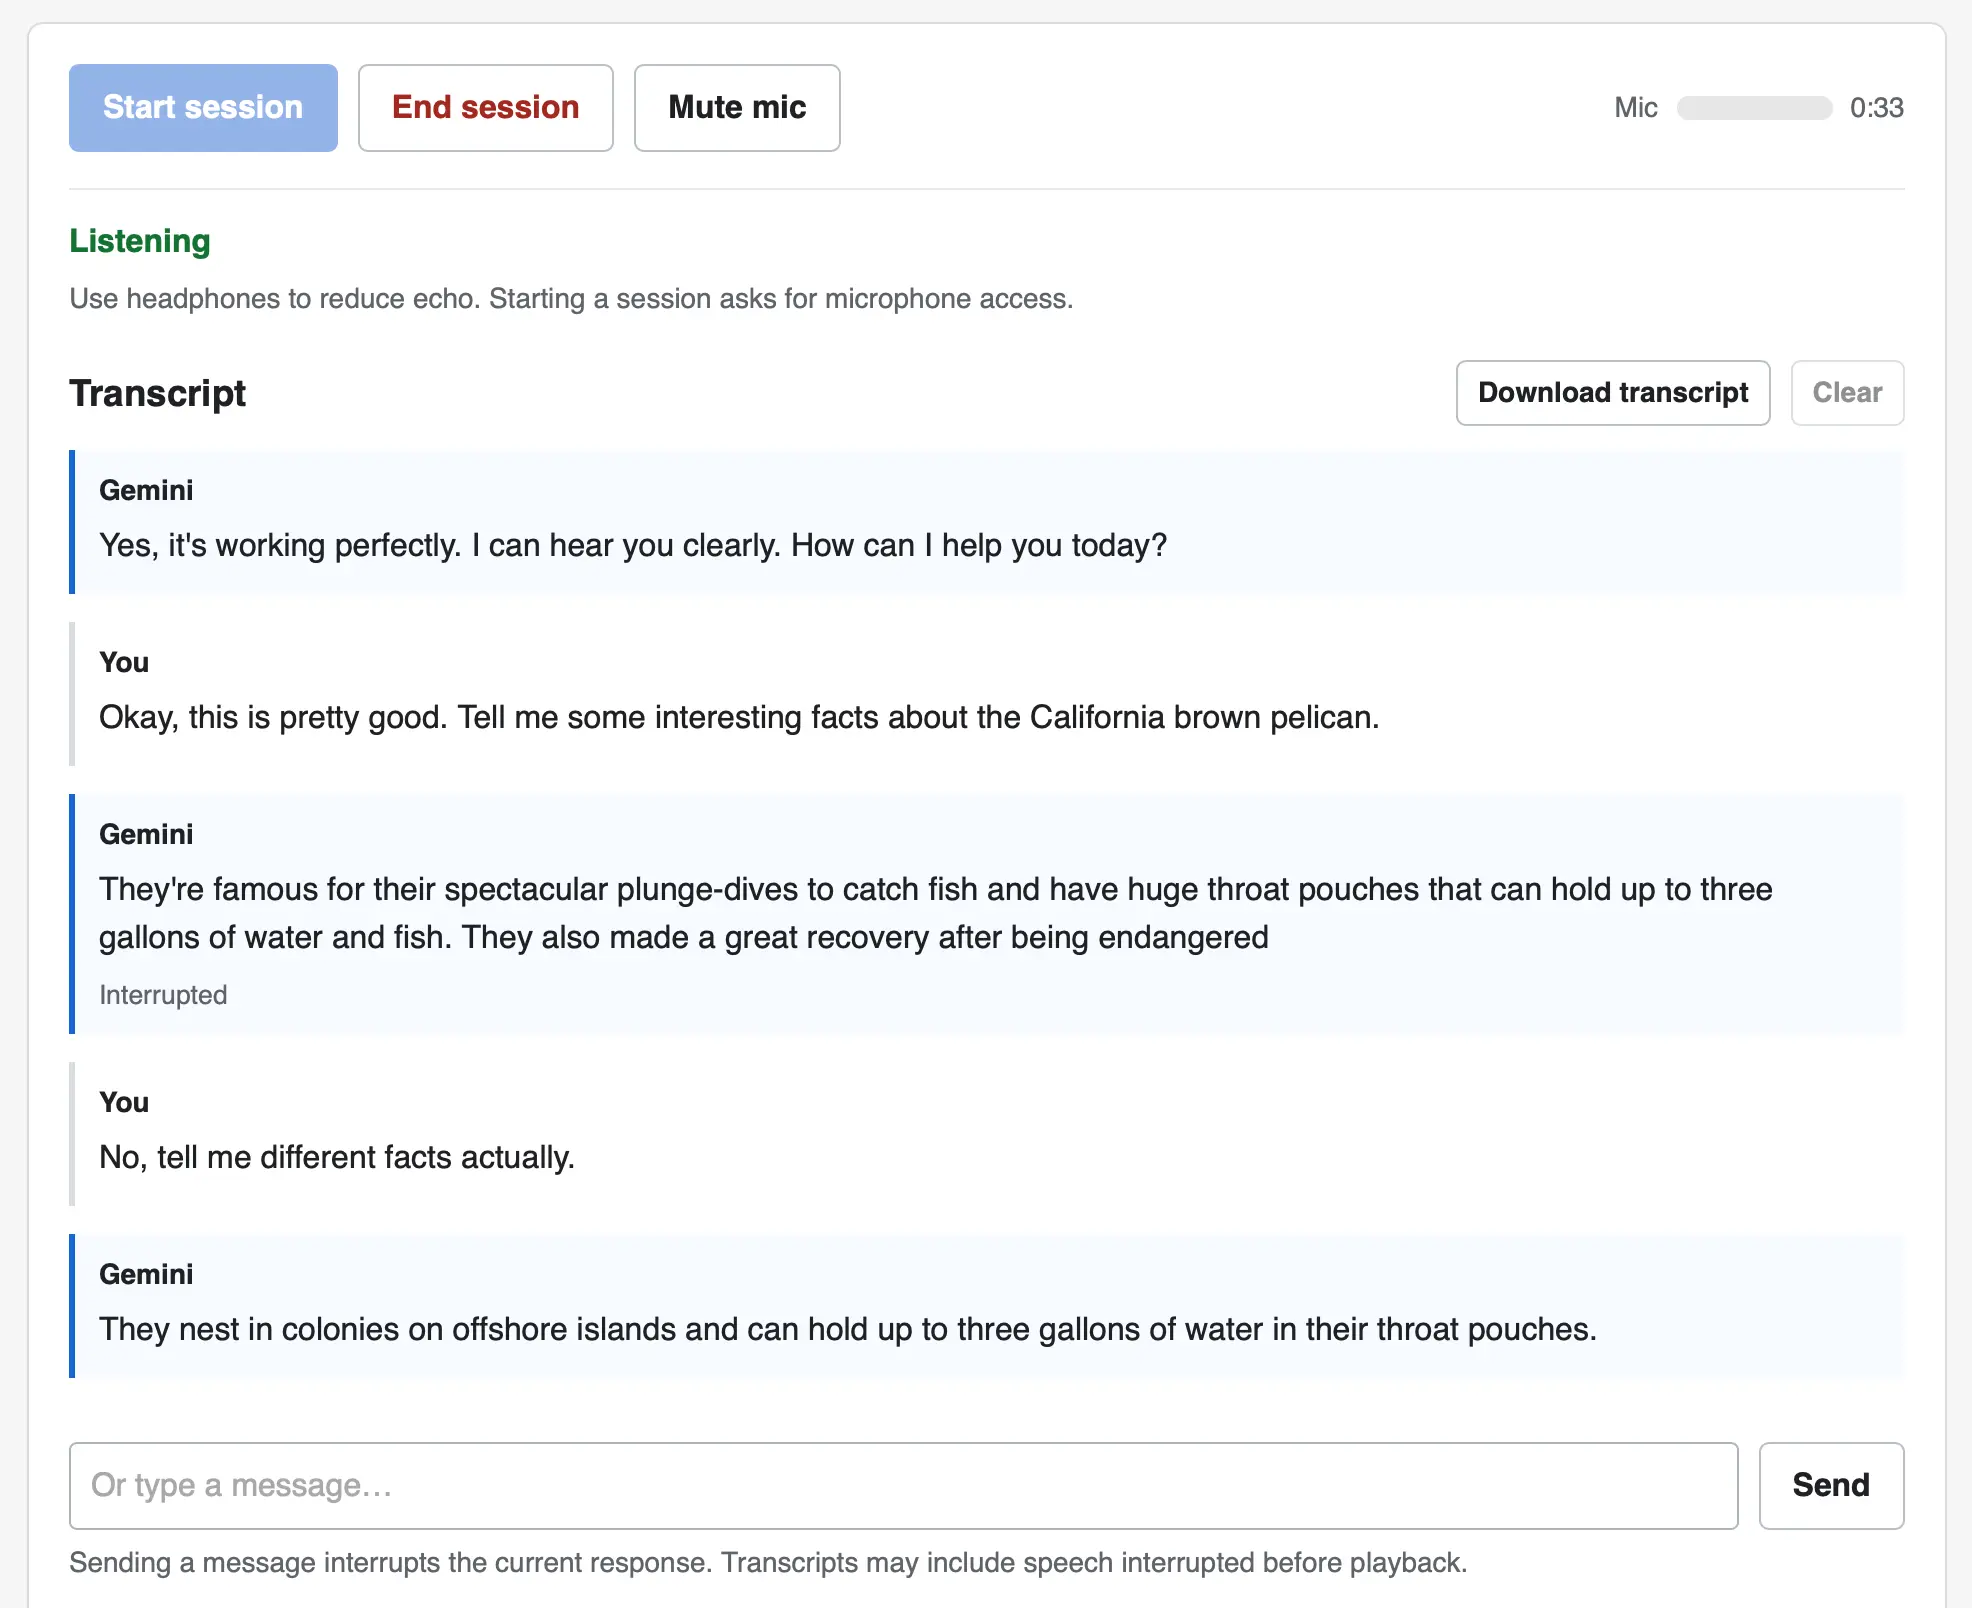
I pointed GPT-6 Astra Extra High at the documentation and had it build me this web UI for trying out the new models. You can select a model and voice preset, enter an optional system prompt and then start a voice conversation through your browser, including the ability to interrupt the model while it is talking.
The implementation uses no libraries. It connects to the wss://generativelanguage.googleapis.com/ws/google.ai.generativelanguage.v1alpha.GenerativeService.BidiGenerateContent?key=... WebSocket endpoint and uses a Web Audio API AudioContext for both capture and playback.
Here's the Gemini Live tutorial for getting started with that WebSockets API.
Fresh dev news, AI-digested daily. Never miss a trend at devoured.fyi