GLM-5.3: How Chinese labs keep stride with the frontier
Z.ai’s GLM-5.3 release demonstrates how Chinese labs maintain competitive parity by prioritizing fast release cycles and aggressive RL-focused post-training over slow, cautious deployment strategies.
Deep dive
- Release Velocity: Z.ai's cycle is measured in days, unlike the months-long pre-release testing at OpenAI or Anthropic.
- RL Focus: The model relies on RL (Reinforcement Learning) environments, which the lab has scaled extensively.
- Capability Diffusion: Cybersecurity features like exploit analysis in GLM-5.3 highlight the dual-use risks and the difficulty of preventing high-level capabilities from leaking.
- Data Sourcing: Evidence suggests Chinese labs are acquiring RL training data environments similar to those used by Western labs.
- Benchmark Strategy: Labs are increasingly purchasing or curating data to optimize performance on specific, high-visibility benchmarks.
Decoder
- RL (Reinforcement Learning): A training technique where the model learns by receiving rewards or penalties based on its output, used heavily to optimize models for specific coding or reasoning tasks.
- Hillclimbing: An iterative process of making incremental improvements to a model to achieve higher scores on performance metrics.
- Benchmaxxing: The practice of hyper-optimizing a model to excel on public benchmarks, sometimes at the expense of general-purpose usability.
Original article
GLM-5.3: How Chinese labs keep stride with the frontier
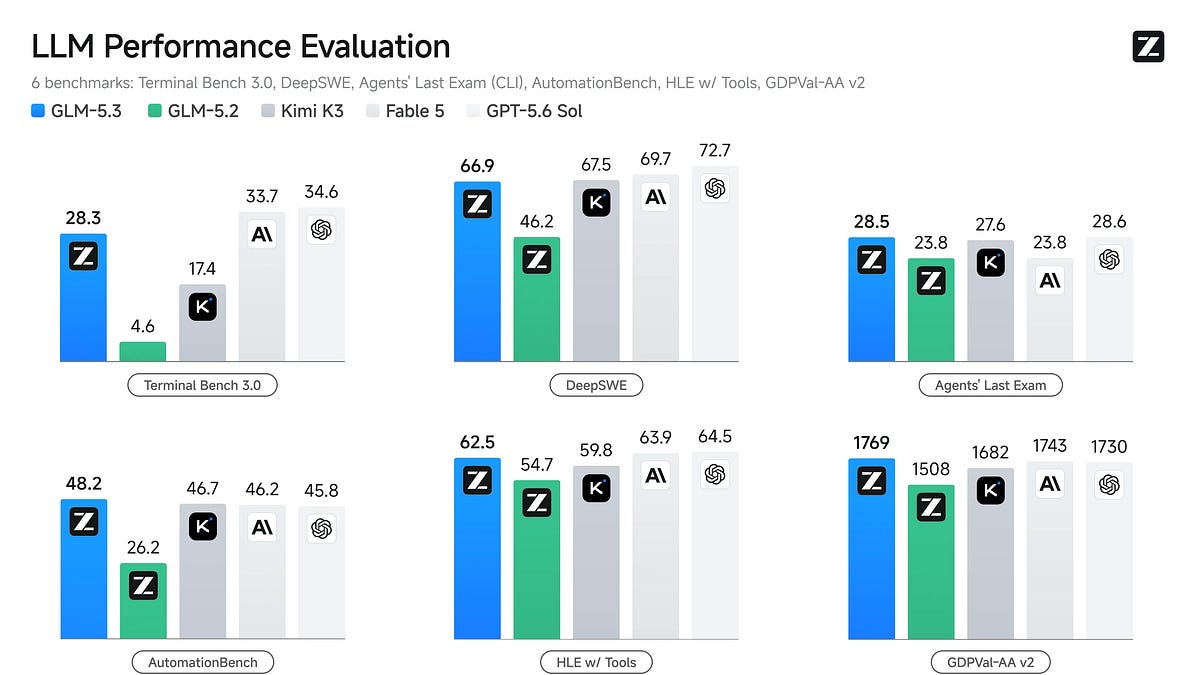
Today, Z.ai announced their GLM-5.3 model, currently only available in the coding plan, coming soon to their API and in two weeks’ time to Hugging Face (open weights). This model looks exceptional, with a somewhat astounding increase in scores. On many benchmarks the model has surpassed Moonshot AI’s Kimi K3 and on some it’s surpassed Claude Fable 5 or GPT-5.6-Sol.
This puts the model more or less at the frontier of agentic coding benchmarks, with only ~750B parameters – a third of Kimi K3! The Z.ai blog post is rather straightforward, and starts with a bold sentence:
Scaling post-training is all we did for GLM-5.3.
GLM-5.3 is the same base model as GLM-5.2 with substantially extended post-training. To risk a broad oversimplification, Z.ai seems to have a strength in post-training when compared to Kimi, which is more of a pretraining masterpiece. Following this release there have been a lot of discussions wondering how China can keep up so well? How can such a small model be matching the leading public American models? Are these results real?
The simplest explanation is that Z.ai is very good at what they do – it’s worth recalling that they’ve been working on this line of models longer than almost anyone in the industry. Here’s a brief history of the GLM models.
- Zhipu AI Founded – 2019
- GLM (General Language Model) — March 2021 — released by THUDM, Tsinghua University’s Data Mining / Knowledge Engineering group.
- GLM-130B — August 2022 — Scaled version.
- ChatGLM — March 14, 2023 — first chat version.
- ChatGLM2 — June 25, 2023
- ChatGLM3 — October 27, 2023
- GLM-4 — January 16, 2024 — rebranded as just GLM; open-weight GLM-4-9B followed in June.
- GLM-5 — February 11, 2026 — latest major generation.
GLM 5.2, released on June 22 of this year, was a big deal – weeks after the release, I regularly heard from AI researchers I know who still used the model due to its speed (some deploy the model on internal clusters for faster speeds than public offerings) and simplicity (as a model with no rollbacks, etc., when working on frontier AI systems). GLM-5.2 altogether stood up to the hype.
I’ve been going through some of the same denial myself, thinking “how do they keep doing this? Surely the models aren’t as good as they look.” There’s something a bit off-putting with how the American companies have such a commanding resource lead, but can’t seem to pull away in capabilities. The common answer is distillation, which I’ve written at length about, but I deem not to be the major factor. On that note, there was a recent paper that showed simple methods for extracting the reasoning traces from frontier models – this is the sort of thing that Chinese labs could definitely use at scale. I’m confused why the labs in the U.S. haven’t patched this behavior faster; instead they’re running to the government asking for policy help. It doesn’t add up for me.
Z.ai’s blog is direct and matches with an RL-dominated training regime. They say they used “more environments, more diverse tasks, and more compute spent training on them.” One does not simply “distill” RL environments, infrastructure to run them at scale, or algorithms to mix them together effectively.
So, how do the Chinese labs do it if not distillation? Are they benchmaxxing? An accepted definition of benchmaxxing is focusing the model on the test sets, such that the real-world performance meaningfully differs from the on-paper scores. The determining factors are much more big picture than technical:
- The time to release for Z.ai is likely days, not months as with OpenAI or Anthropic. It is very, very likely that OpenAI and Anthropic have far better internal models than Z.ai and Moonshot AI. Still, these American companies tend to take months to release their models to the public, which massively flatters the Chinese labs in adoption decisions at the frontier. To put it simply – the Chinese labs use all the time that American labs do pre-release testing to keep hillclimbing on benchmarks (SpaceXAI is likely far closer to the Chinese labs here). With the pace of progress being so fast, this is likely the largest determining factor of why Chinese labs stay at the frontier. This, so far, has been economically acceptable for the American labs, as they’ve still had massive demand for their models.
- Yes, Z.ai probably cares slightly more about public benchmarks than OpenAI or Anthropic. These benchmarks, e.g. scoring highly on the Artificial Analysis Intelligence Index, or similar aggregators, have a very direct impact on their stock price. They in many ways need to do this to keep raising capital and maintain team morale, as being the scrappy underdog matching American giants is a wonderful story. Subtle benchmaxxing does not need to come out of desperation or any similar pressures. It’s the industry standard across a remarkable number of labs.
- Z.ai is not benchmaxxing to the point where GLM-5.3 is fried (at least not intentionally, and they’ll check for it). Every lab is dealing with the rough edges of scaling RL right now. Anthropic’s Opus 5 and Sonnet 5 models have very mixed reputations, despite the incredible benchmark scores. Everyone in the industry is in the same boat, so some model weights end up being easier to use than others, but the benchmark scores in their release blogs are the real deal.
- GLM-5.3 is likely a narrower model than Claude Fable or GPT Sol. When GPT-5.2 was released, it had mixed reviews outside of agentic coding. At the same time, OpenAI and Anthropic support very large businesses with countless use-cases for their models. This is a benefit of being a company earlier in their adoption curve – you can target the most valuable use-cases. Within post-training, caring about a bit less will make assembling the final model far easier.
- The RL data industry is taking off in China. Many sources and rumor-mills we’re following have been mentioning how the data industry is taking off in China — very much driven by American data companies selling to Chinese model labs. This could look like Chinese labs buying many of the same RL environments that are used by American frontier labs, and releasing the downstream RL’d model sooner. We still have large error bars on the scale and impact of this market, but it is certainly becoming important.
- Z.ai is an extremely skilled LLM organization – one that is likely far more compute efficient than OpenAI / Anthropic. This needs repeating. These folks are very good at what they do. The company has very close ties to Tsinghua University, which is home to many of the best Chinese computer scientists. This abundant, eager talent pool is as central to their success as it is for any Western counterpart.
Altogether, it seems like a perfectly good strategy they’re executing with the GLM line of models. Congrats on the release! I’m excited for the weights to be out so I can do more extended testing.
This is another step towards the inevitable proliferation of very strong cyber capabilities across the economy. Z.ai has acknowledged this, saying:
GLM-5.3 is our most capable model to date for cybersecurity tasks. It delivers substantial improvements in vulnerability discovery, exploit analysis, and complex multistep security tasks. These capabilities can help defenders identify weaknesses earlier, validate risks, and accelerate remediation.
They also create clear dual-use risks. We are therefore taking a staged approach to release. Selected security partners will first evaluate GLM-5.3 in controlled settings. Broader access and API availability will follow. Once the necessary safety evaluations and release preparations are complete, we will publish GLM-5.3’s complete model weights.
They go on to acknowledge how they’re monitoring inference on their platforms via a request classifier and chain of thought monitoring (on top of model alignment). The devil is in the details here, and it is unclear the level of execution every AI lab will have here. The capability diffusion is determined by the lowest common denominator.
At the end of the day, this type of safety barely matters when true open-weights are coming. If not GLM-5.3, then another model. The size of the models with these capabilities is reducing over time, becoming easier to modify and deploy (potentially without safeguards). Z.ai does some of the right things, including pushing for more vulnerability discovery and proactive management, but any single company is far from being able to handle this on their own.
We need industrial-scale guidance led by the government or industry coalitions to immediately prepare for this transition across all software.
Fresh dev news, AI-digested daily. Never miss a trend at devoured.fyi