Applied Compute Agent Cloud
Applied Compute is positioning itself as the 'model factory' for enterprises with the launch of its Agent Cloud (AC2).
Deep dive
- AC2 allows teams to switch between various open-source models without changing the underlying training or serving infrastructure.
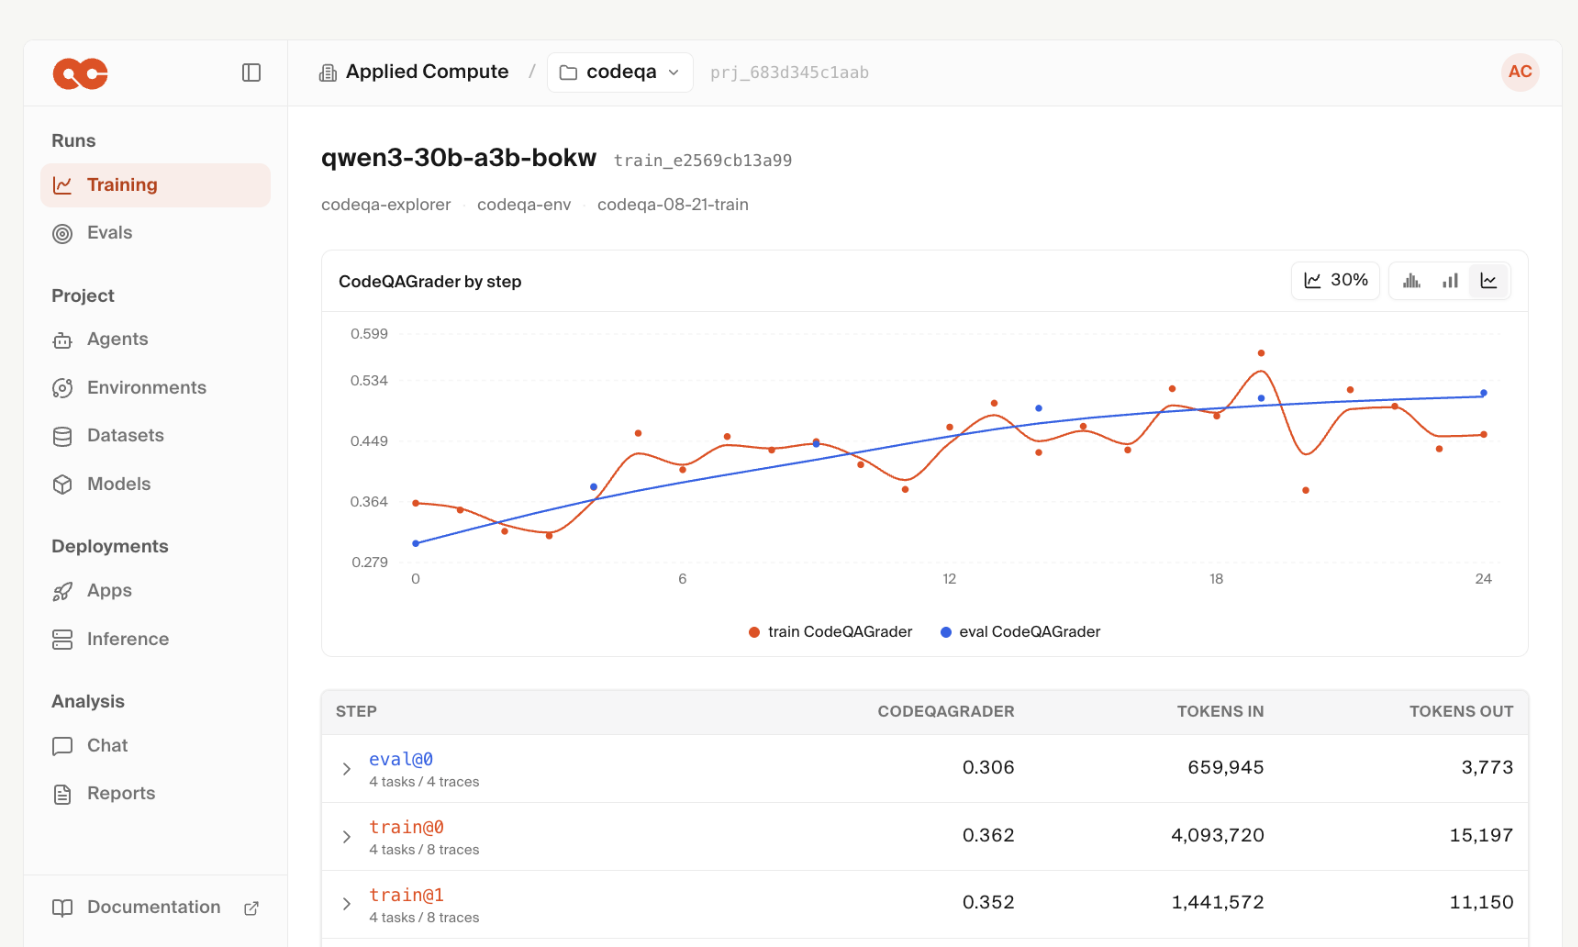
- Provides a 'researcher cockpit' to visualize model rollouts and debug reinforcement learning (RL) agents.
- Built-in 'Ari' research agent monitors model health and suggests improvements based on failure modes.
- Inference engine supports speculative decoding and autoscaling to manage cost and latency.
- Closes the feedback loop by using production traffic to generate learning signals for future model iterations.
Decoder
- Speculative Decoding: A technique to speed up model inference by using a smaller, faster model to draft predictions, which the larger, accurate model then verifies in parallel.
- On-policy self-distillation: A training method where an AI model uses its own past outputs or production successes to generate training data for its future versions.
- RL (Reinforcement Learning): A training paradigm where models learn by receiving rewards for specific actions in an environment to optimize behavior over time.
Original article
To put the next frontier within reach of every team, we’re launching AC2: the Applied Compute Agent Cloud. AC2 is the internal platform our own researchers use to build custom state-of-the-art models for customers like Microsoft, NVIDIA, Cognition, Mercor, DoorDash, Harvey, and others.
AC2 gives every AI team one platform to train open models, serve them at scale, and bring everything they encounter in production into the next run. Every company should build intelligence powered by its own data and designed for its own work.
Here’s what you should know about AC2.
Build your model factory
Open models are improving at an extraordinary pace. More capable weights ship every month, expanding what teams can build while making any single model less durable as an advantage.
Your company won’t win by choosing the best model, but by building a model factory: a repeatable process to turn your data into model improvements. With AC2, companies can now go beyond customizing at the prompt level to customizing models themselves, each suited to a company’s unique workflows and specific needs.
Choose what’s right for your team
AC2 supports all the latest open models, allowing teams to choose the right starting point for each workload based on capability, speed, and cost. As new weights are released, teams can evaluate them quickly and move to a better foundation without rebuilding their stack.
AC2 also allows you to bring your own harness for training. You can start training with a few dozen lines of code, empowering your researchers to focus on experiments and data instead of infrastructure.
Turn experimentation into a repeatable, engineered process
Training RL models is as much of an art as it is a science. Accordingly, researchers often need to take a look at what a model is trying to do to debug issues in the environment, graders, and the agent’s behavior. The AC2 console is a researcher cockpit to examine rollouts, compare runs, and iterate on graders.
Our frontier-grade post-training stack was written to maximize GPU performance without sacrificing ML stability. Our RL control plane adapts the workload to scale ups in training compute and context length, allowing you to add compute and immediately achieve high utilization.
Ari, our applied research agent, works alongside your team throughout the training loop to analyze results, uncover failure modes, and turn each finding into better data for the next experiment. Ari monitors run health, reads through rollouts, and takes action even when you’re offline.
Deploy on dedicated inference capacity
Our serving stack can be optimized end-to-end for your workload, balancing latency, throughput, and cost while autoscaling replicas as traffic changes.
Because training and serving happen on the same platform, production endpoints use the same sampling configuration, numerical precision, and kernels used during training. Each deployment is also tuned to the latency and throughput requirements of your workload. From a completed run, you can deploy your checkpoint in minutes with 99.9% uptime, autoscaling, and low latency inference using speculative decoding.
New checkpoints can be deployed behind the same endpoint within minutes, without changing your API, routing, access controls, or observability.
Models that continuously improve
The most valuable data often arrives after deployment: real user interactions, corrections, and feedback. Once serving is live, you can capture this data for continued training and improvement. Production traces can help you identify failure modes, build new data points, generate hints for self-distillation, and guide the next training run.
On-policy self-distillation in AC2 lets you learn from production traffic even when the original environment cannot be replayed. You can use traces and user interactions to generate learning signals for the next model.
The result is intelligence that grows more capable, more efficient, and more specific with every interaction. AC2 gives AI teams the infrastructure to train, serve, and improve their own intelligence.
AC2 is now available in private beta. Reach out to learn more or join us if you’d like to help build the platform to train and serve open weights.
Fresh dev news, AI-digested daily. Never miss a trend at devoured.fyi