Popping the GPU Bubble
Moondream's Photon engine achieves near-realtime inference by pipelining CPU housekeeping underneath GPU math loops, eliminating idle 'GPU bubbles'.
Deep dive
- Identifies 'GPU bubbles' where the GPU idles while the CPU performs necessary metadata and batch-management tasks.
- Implements 'ping-pong slots' (dual buffers) to allow GPU work for step 't+1' to begin while the CPU is still finalizing step 't'.
- Uses 'forward now, sample later' to allow GPU compute to proceed before the sampling mask is fully determined.
- Introduces a 'zombie' refcounting system to manage sequence completion without breaking the pipelined flow.
- Demonstrates up to 35% higher throughput on NVIDIA B200 hardware through these architectural optimizations.
Decoder
- GPU Bubble: A period of idle time where the GPU waits for the CPU to finish tasks (like metadata selection or kernel launching) before proceeding to the next mathematical step.
- Autoregressive: A method of sequence generation where the next token (chunk of text) depends on the previous ones, necessitating a sequential loop.
- KV Cache (Key-Value Cache): A memory optimization that stores previously computed attention keys and values to prevent recalculating them for every new token.
Original article
Popping the GPU Bubble
Photon, Moondream's inference engine, achieves near-realtime VLM inference (~33ms on NVIDIA B200). This is a peek into how it delivers up to 35% higher decode throughput by optimizing how the GPU works.
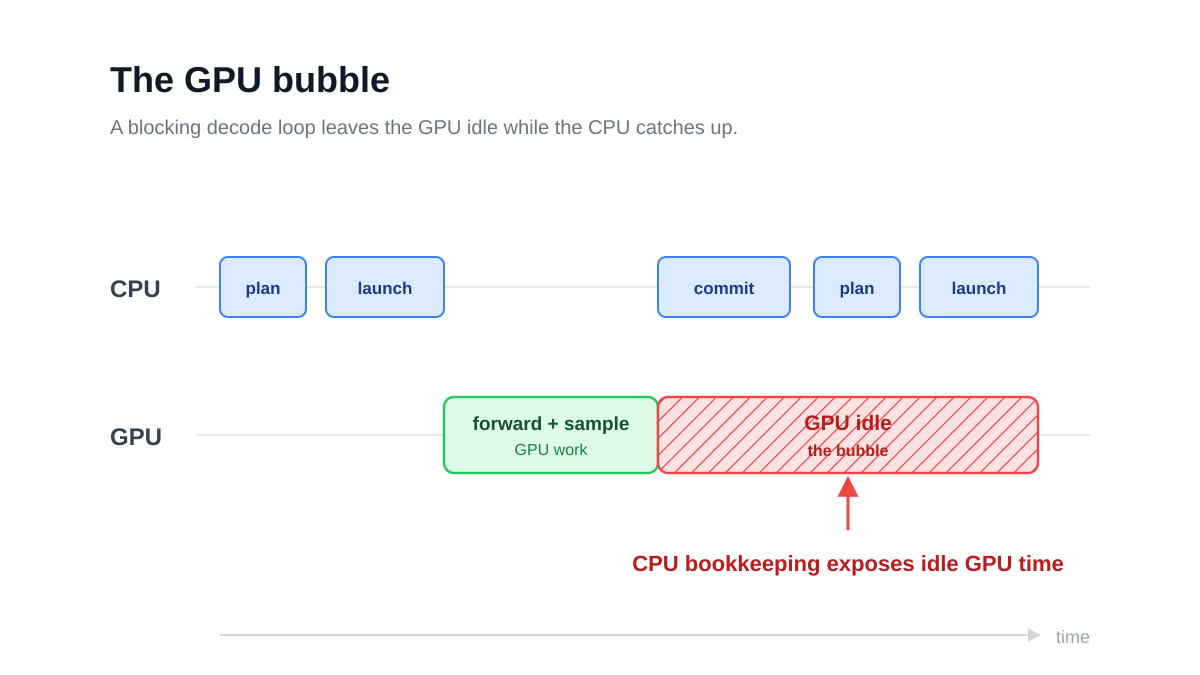
How do you make an AI model run as fast as possible? This is a question we obsess over at Moondream HQ. The GPU handles all the math involved in model inference, so at first glance it doesn't seem like there's much to it: just tell it what to do and wait for the answer. But if you start looking at how it actually works under the hood, you find that the GPU often sits idle, not for lack of work, but because the CPU hasn't told it what to do next yet. This phenomenon is called a GPU bubble.
When a typical AI model generates text, it produces one token at a time (a token is a chunk of text, roughly a few characters). Each token depends on the tokens before it, a property called autoregressive, so generation is sequential. You can't compute the third token before you have the second. This decode loop involves a round trip between the CPU and GPU. The GPU does most of the heavy lifting to run the actual model, performing billions of arithmetic operations to produce the next token. But there's also a surprising amount of work done by the CPU. It selects which requests to run next, sets up the metadata the GPU needs for them, picks the actual token out of the model's output and records it, and more.
The challenge is that one token's worth of GPU work is small, while the CPU housekeeping is a fixed cost paid on every trip. If the GPU has to wait for that housekeeping before it can start the next token, it sits idle for part of every loop. This is why we get GPU bubbles.
In this post we're going to dive into how Photon hides these bubbles using a technique called pipelined decoding. The idea is to overlap the two kinds of work: we start GPU work on the next token while the CPU is still finishing the last one.
The bubble
Here's the shape of the problem.
In the blocking version (top), every step is a baton pass. The CPU plans and launches a forward, the GPU runs it, then the CPU synchronizes, waits for the results to land, commits them, and only then starts planning the next step. This is because the plan depends on the token we select. For example, if the model indicates it has finished answering, then we need to schedule a new pending request from our queue. The GPU sits idle waiting for the CPU to finish its commit-plan-launch work.
The fix is to pipeline the loop. Launch the next forward while the current step's token is still coming back and being committed. That's the pipelined version (bottom): the forwards run back-to-back, and the CPU work is overlapped underneath them.
The reason we can is that the token we just sampled doesn't have to leave the GPU. The next forward reads it straight from GPU memory as its input. We still want a copy on the CPU eventually, to detokenize it, stream it, and decide whether the request is done, but that is bookkeeping we can do a moment later, in the background, while the next forward already runs. Not waiting on that copy is the move that removes the bubble.
Mechanism 1: ping-pong slots
To run a decode step, the GPU needs a working set of buffers: a place to stage the input (the last generated token and its position in the sequence), a place for the model to write its output (the logits, one score per word in the vocabulary), a place to land the sampled token, and some bookkeeping the attention kernel needs to find each sequence's cached keys and values (its KV cache). We keep pinned (page-locked) host buffers on both ends, so the copies on and off the GPU run as background DMA (direct memory access) transfers instead of blocking the CPU.
These buffers are allocated once and reused on every step. We work hard to avoid performing GPU memory allocations at runtime, because they can cause device synchronization and introduce bubbles. Fixed buffer addresses are also needed for capturing the decode step once as a CUDA graph and replaying it, reducing kernel launch overhead. We call this bundle a DecodeSlot.
This works, but introduces a blocker for pipelining. The buffers stay in use until the step is done, so we cannot start the next step until the current one finishes. To overlap two steps, the second step needs its own working set, otherwise it can overwrite the results of the first step before the CPU has read them. So we keep two slots and alternate between them, ping-pong style.
One thing to note about launch: we don't execute kernels the instant we issue a launch from CPU. Instead, we enqueue them onto a stream -- an ordered queue that the GPU drains in order. Work on the same stream runs sequentially, while work on separate streams can overlap. Both slots put their forwards onto the same compute stream. The slots are not for GPU parallelism. They only exist so the CPU can process one slot's results while the GPU runs the other slot's forward.
The forwards all share that one compute stream, but the copies do not. Each step's device-to-host copy, the one that brings the sampled token back for bookkeeping, goes on a separate copy stream, so it can run while the GPU is busy with the next forward. That is what lets us not wait for it. We anchor the copy to an event recorded the instant the step's outputs are written, so it waits on exactly that step's work and nothing queued behind it.
A slot only becomes free once its results have been read, not just once the GPU is done with it. Its pinned host buffer is the landing site for a copy that may still be in flight, so handing the slot to a new step too early would overwrite a copy mid-transfer, creating a hard-to-debug corruption bug. So the slot stays reserved through the commit that reads it, and is released only once that commit has finished.
Mechanism 2: forward now, sample later
The next forward can run ahead because it doesn't depend on anything the CPU does with the last token. But two things about the next step do depend on the last step's committed result. One is which sequences are still in the batch: if a request just finished, it shouldn't be in the next forward. That is the next section (zombies). The other is what tokens the next step is even allowed to sample, and that one is this section.
It comes from constrained decoding. Moondream's spatial skills return structured output instead of free text: point returns a coordinate, detect returns boxes, segment returns an outline. We get those from the same decode loop by restricting which tokens the model may produce at each step: we force the scores (the logits) of the disallowed ones to negative infinity before we sample. A point step has to emit a coordinate, a detect request walks an x, y, size cycle, and so on. Which tokens are allowed, the mask, depends on what has been produced so far, so the mask for step t+1 depends on the token we sampled at t.
The dependency is in sampling, not in the forward.
Each scheduler tick goes through three phases: launch, commit, and finalize:
- Launch the forward for t+1. It doesn't depend on the mask, so it goes immediately.
- Commit step t: wait on the in-flight copy and advance the request's decode state. That is needed to decide the mask for t+1.
- Finalize sampling for t+1: with the state current, build the mask and sample.
Sampling t+1 lands after committing t because the commit is what makes t+1's mask correct. We call this "commit-before-finalize" ordering. The GPU runs the t+1 forward through steps 2 and 3, so the commit disappears from the critical path.
For plain text there is no mask, so forward and sampling can both run a step ahead. For constrained sequences the forward still runs ahead, but sampling waits on the previous commit, which caps how far ahead we get with no special-casing. One loop handles both.
Mechanism 3: zombies: finalize early, release late
Back in forward now, sample later we flagged two ways the next step depends on the last step's committed result. The sampling mask was one. Batch membership is the other, and it takes a bit of care to handle right.
To launch step t+1 we first decide its batch, which sequences are in it, and we do that before committing step t. So what happens when a sequence hits its stop token at t, but is already baked into t+1's forward? You can't un-launch GPU work. The sequence is finished, yet still physically present in a batch that's executing.
Photon calls these zombies, and instead of bolting on cancellation logic, it lets the behavior emerge from two per-sequence fields:
finalized:Trueafter the sequence has hit EOS or its length cap.inflight_refs: the number of in-flight steps that still reference this sequence (0, 1, or 2).
When step t commits and detects EOS, the sequence is marked finalized and its result is emitted — but it isn't torn down, because inflight_refs is still nonzero (step t+1 references it). At step t+1's commit, the sequence is already finalized, so the commit is skipped: no token is appended, no state mutates. The zombie was harmlessly along for the ride — it occupied its slot and wrote some KV that nobody will read. Only when inflight_refs finally hits 0 are its KV pages and LoRA slot released.
This finalize-early, release-late dance is a small amount of refcounting that replaces what would otherwise be a thicket of "cancel this row mid-flight" special cases.
Prefill rides the same pipeline
So far this has all been about decode steps, but a real serving loop is constantly doing two different kinds of work: prefill (processing a new request's prompt + image, the expensive one-shot forward over many tokens) and decode (one token at a time for everyone already running).
Photon doesn't separate them. A prefill is just another kind="prefill" launch in the same two-slot pipeline. Because the pipeline only cares that a slot is free, not what kind of work last used it, a prefill forward can be launched into one slot while a decode step from the other slot is still being committed, and vice versa. The expensive prefill forward runs on the GPU while the CPU commits decode results; the next decode forward runs while the CPU finishes admitting the just-prefilled request. The same commit ordering (and the same inflight_refs bookkeeping) keeps everything correct across the two kinds, so none of the zombie or constrained-decode logic needs a special case for "what if a prefill is in flight."
A cost model for the bubble
How much should pipelining actually buy you? You can predict it from the parts of a decode step, and then check the prediction against measurement.
A decode step is three pieces of work:
- forward: the heavy GPU matmuls. At decode this is memory-bandwidth bound: every token streams the whole weight set through the cores, so it has a floor near
weight_bytes / memory_bandwidth. It shrinks as memory gets faster or as the model gets smaller. - sampling: turning the scores into a committed token: the constrained-decode mask, the argmax/sample, the spatial (grounding) decode, and the device→host copy of the result. All GPU work.
- bookkeeping: the CPU around it. Choose the next batch (
plan), launch the graph (launch), commit the previous step (commit).
A blocking loop runs the three in series, so the GPU sits idle through the bookkeeping — that idle is the bubble. Pipelining slides the bookkeeping of one step underneath the forward + sampling of the next, so the period collapses toward forward + sampling and the bubble disappears. Measured per step, pipelined, that's exactly what we see — the GPU is busy for essentially the whole period (steady-state medians, moondream2, ms):
| forward (ms) | sampling (ms) | period (ms) | |
|---|---|---|---|
| 3090 · 1 stream | 4.87 | 0.20 | 5.10 |
| 8 streams | 6.66 | 0.27 | 6.97 |
| 32 streams | 10.24 | 0.26 | 10.52 |
| B200 · 1 stream | 2.45 | 0.14 | 2.63 |
| 8 streams | 3.12 | 0.14 | 3.30 |
| 32 streams | 3.80 | 0.14 | 3.98 |
speedup  =   T_block / T_pipe    ×      (1 − z)
            └─ bubble hidden ─┘     └─ zombie tax ─┘
| blocking (ms) | pipelined (ms) | L | predicted | observed | |
|---|---|---|---|---|---|
| 3090 · 1 stream | 5.44 | 5.10 | 104 | +5.7% | +6.5% |
| 8 streams | 7.52 | 6.97 | 113 | +7.6% | +7.8% |
| 32 streams | 11.74 | 10.52 | 113 | +11.1% | +11.6% |
| B200 · 1 stream | 3.11 | 2.63 | 115 | +17.2% | +17.6% |
| 8 streams | 4.04 | 3.30 | 115 | +22.2% | +21.9% |
| 32 streams | 5.55 | 3.98 | 104 | +39.1% | +35.4% |
It's never just one thing
That's the whole technique: ping-pong slots so two steps don't collide, a forward/sampling split so even constrained decoding can run ahead, and a little zombie refcounting so finished requests tear down cleanly. The GPU stops waiting on the CPU, and you get back anywhere from a few percent to a third; more the faster your accelerator/model is.
But Photon isn't fast because of this one technique, or any single technique. It's fast because dozens of these details compound across the serving stack: how we resize and tile images on the way in, the kernels that run the model, the scheduler ordering here, and the synchronization points we remove from the hot path. No one piece is the whole story; the stack gets fast when enough of them line up.
Fresh dev news, AI-digested daily. Never miss a trend at devoured.fyi