DEVOURED
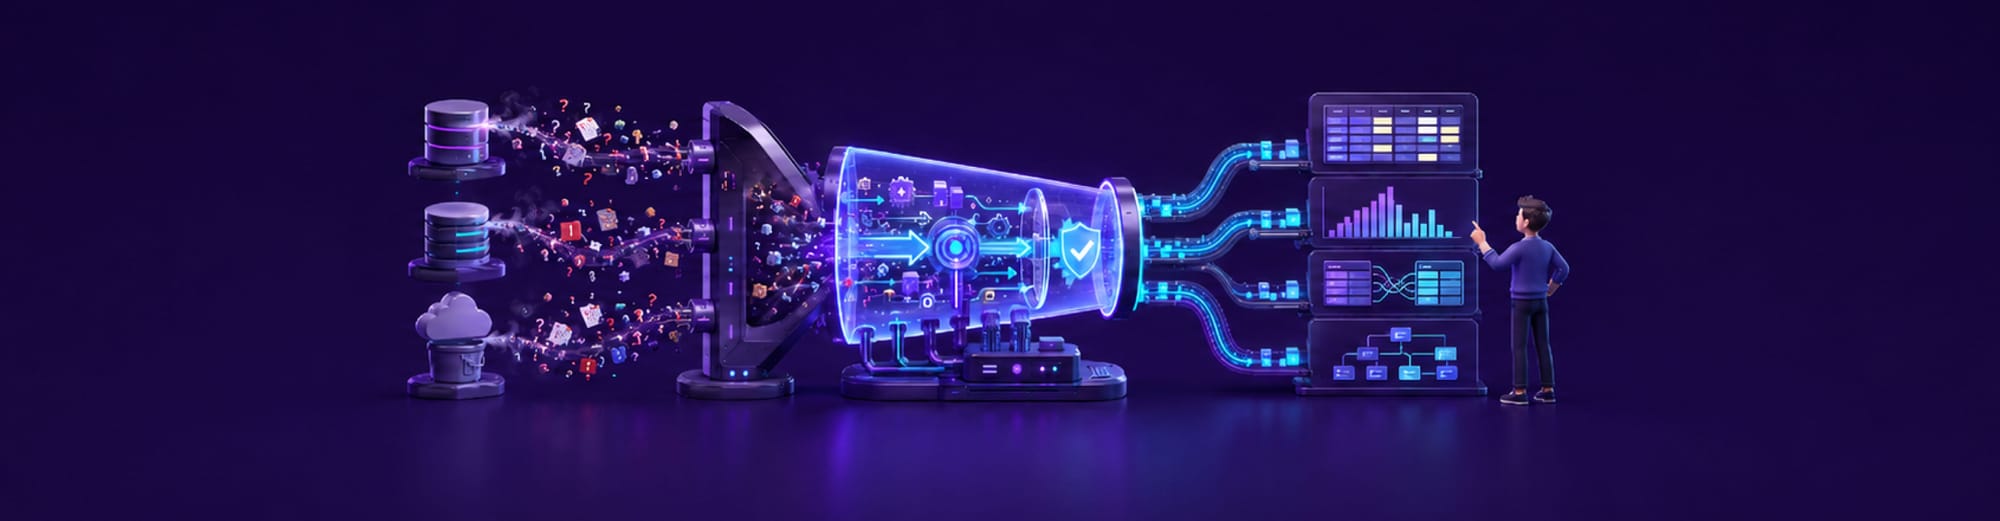
Enabling Data Intelligence: Data Profiling Framework at Halodoc
Halodoc built an Airflow-native data profiling framework to automate data quality checks, join intelligence, and source table analysis across hundreds of tables.
What: Halodoc's Data Engineering team created an Airflow-native framework to automate column-level profiling, join intelligence extraction via SQLGlot, and source table analysis using information_schema. It runs compute on Redshift/Athena, isolating tasks in Kubernetes pods, and writes idempotent staging data using a `run_id` pattern.
Why it matters: This framework transforms data understanding from a manual, time-consuming process involving ad-hoc SQL into a self-serve, automated system, giving engineers and analysts a reliable, historical view of data quality and relationships, crucial for large, distributed data ecosystems.
Takeaway: If your data team spends significant time on manual data quality checks or struggling with join discovery, consider implementing a similar Airflow-native, config-driven data profiling framework with pushdown compute and idempotent staging writes.
Deep dive
- Halodoc faced issues like lack of column-level visibility, late discovery of join failures, no historical baseline for data regressions, and engineers being bottlenecks for data questions.
- Data profiling collects statistics and metadata on structure, content, and quality, covering null checks, uniqueness, distribution, and schema.
- The framework has three main components: Column-Level Profiler, Join Intelligence, and Source Table Analyser.
- Compute is pushed down to Redshift or Athena, and tasks are isolated in Kubernetes pods using Airflow's dynamic task mapping.
- Results are stored in Redshift for central querying and visualization via Metabase dashboards.
- The framework is config-driven, allowing new tables to be profiled via JSON configs without code changes.
- Column-Level Profiler: Generates dynamic SQL to compute null percentages, distinct counts, min/max, length ranges, and numeric stats in a single table scan. It also provides value distribution and sample records.
- Join Intelligence: Extracts join relationships directly from production SQL files in S3 using SQLGlot for AST traversal, supporting dialect detection and fallback strategies.
- Source Table Analyser: Profiles source systems safely by using
information_schemaand engine metadata, avoiding full-table scans on OLTP databases. It also combines Hudi metrics for partition recommendations and compaction insights. - Implementation ensures operational safety and scalability via a "validation first" Airflow DAG structure and idempotent staging table writes using a
DELETE+COPY+INSERTpattern with a uniquerun_id. - Impact included reducing column understanding time from an hour to 10 minutes, join discovery from 30-60 minutes to under 10, and proactively identifying regressions and compaction issues.
- Challenges included SQL diversity (macros, mixed dialects), parser fallbacks, staging table concurrency, and approximate
information_schemarow counts.
Decoder
- Data Profiling: The process of examining datasets to collect statistics and metadata that describe their structure, content, and quality, to improve data understanding and identify issues.
- Airflow: An open-source platform to programmatically author, schedule, and monitor workflows, often used for data orchestration.
- Redshift: Amazon's cloud data warehouse service.
- Athena: Amazon's serverless query service that allows querying data directly in Amazon S3 using standard SQL.
- SQLGlot: A SQL parser, transpiler, and optimizer written in Python, capable of converting SQL between different dialects and building abstract syntax trees (ASTs).
- AST (Abstract Syntax Tree): A tree representation of the syntactic structure of source code, used in SQLGlot to parse and analyze SQL queries.
- Jinja macros: Templating language constructs used to generate dynamic content, often found in SQL queries within data pipelines.
- OLTP (Online Transaction Processing): A class of software systems that facilitate and manage transaction-oriented applications, typically characterized by many concurrent, short online transactions.
- Hudi: An open-source data lake platform that provides ACID transactions, upserts, and deletes on large datasets stored in object storage like S3.
Original article
Full article content is not available for inline reading.
Explore all 68 articles in today's digest
Fresh dev news, AI-digested daily. Never miss a trend at devoured.fyi