Gemini 3.5 Flash: more expensive, but Google plans to use it for everything
Google's new Gemini 3.5 Flash, despite a significant price increase, is immediately available and slated for broad integration across Google's consumer and developer products.
Deep dive
- Gemini 3.5 Flash is immediately available for general use, bypassing a preview phase.
- It maintains most features of the Gemini 3.x series but lacks "computer use" functionality.
- The model's knowledge cutoff is January 2025, with large token windows (1,048,576 input, 65,536 output).
- Pricing for 3.5 Flash is significantly higher, costing 3x Gemini 3 Flash Preview and 6x Gemini 3.1 Flash-Lite, bringing it close to Gemini 3.1 Pro.
- Google intends to use 3.5 Flash extensively across its free consumer products (Gemini app, Google Search AI Mode) and developer platforms (Antigravity, Gemini API, Android Studio).
- This price increase is part of a broader industry trend, with OpenAI's GPT-5.5 and Claude Opus 4.7 also seeing price hikes.
- A new Interactions API, designed for server-side history management, is currently in beta.
Decoder
- Knowledge cut-off: The date up to which a language model has been trained on data, and therefore the limit of its explicit knowledge.
- Tokens: The basic units of text (words, subwords, or characters) that language models process. Input tokens are consumed by the model, output tokens are generated.
Original article
Gemini 3.5 Flash: more expensive, but Google plan to use it for everything
Today at Google I/O, Google released Gemini 3.5 Flash. This one skipped the -preview modifier and went straight to general availability, and Google appear to be using it for a whole lot of their key products:
3.5 Flash is available today to billions of people globally:
- For everyone via the Gemini app and AI Mode in Google Search
- For developers in our agent-first development platform Google Antigravity and Gemini API in Google AI Studio and Android Studio
- For enterprises in Gemini Enterprise Agent Platform and Gemini Enterprise.
As usual with Gemini, the most interesting details are tucked away in the What’s new in Gemini 3.5 Flash developer documentation. It mostly has the same set of platform features as the previous Gemini 3.x series, albeit with no computer use. The model ID is gemini-3.5-flash. The knowledge cut-off is January 2025, and it supports 1,048,576 input tokens and 65,536 maximum output tokens.
Google are also pushing a new Interactions API, currently in beta, which looks to me like their version of the patterns introduced by OpenAI Responses—in particular server-side history management.
The price has gone up
Gemini 3.5 Flash is accompanied by a notable price bump. The previous models in the “Flash” family were Gemini 3 Flash Preview and Gemini 3.1 Flash-Lite. The new 3.5 Flash is 3x the price of 3 Flash Preview and 6x the price of 3.1 Flash-Lite (see price comparison here).
At $1.50/million input and $9/million output it’s getting close in price to Google’s Gemini 3.1 Pro, which is $2 and $12.
The Gemini team promise that 3.5 Pro will roll out “next month”—presumably at an even higher price.
This fits a trend: OpenAI’s GPT-5.5 was 2x the price of GPT-5.4, and Claude Opus 4.7 is around 1.46x the price of 4.6 when you take the new tokenizer into account.
Given the price increase it’s interesting to see Google roll it out for so many of their own free-to-consumer products. It feels like all three of the major AI labs are starting to probe the price tolerance of their API customers.
Artificial Analysis publish the cost to run their proprietary benchmark against models, which is a useful way to take things like tokenization and increased volume of reasoning tokens into account. Some numbers worth comparing:
- Gemini 3.5 Flash (high): $1,551.60
- Gemini 3.1 Pro Preview: $892.28
- Gemini 3 Flash Preview (Reasoning): $278.26
- Gemini 3.1 Flash-Lite Preview: $93.60
Running the benchmark for 3.5 Flash (high) cost significantly more than 3.1 Pro Preview!
Here are some numbers from other vendors:
- Claude Opus 4.7 (Adaptive Reasoning, Max Effort): $5,117.14
- Claude Opus 4.7 (Non-reasoning, High Effort): $1,217.23
- GPT-5.5 (xhigh): $3,357.00
- GPT-5.5 (medium): $1,199.14
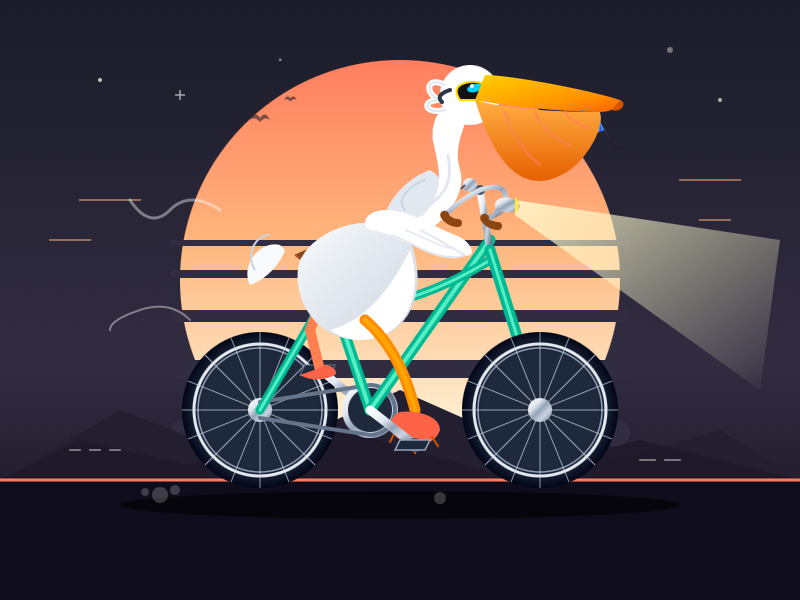
A pelican on a bicycle
I ran “Generate an SVG of a pelican riding a bicycle” against the Gemini API and got back this pelican, which is a lot:
From the code comments: <!-- Pelican Eye / Sunglasses (Cool Retro Aviators) -->
hedgehog on Hacker News:
That pelican looks like it’s in Miami for a crypto conference.
That one cost me 11 input tokens and 14,403 output tokens, for a total cost of just under 13 cents.
Fresh dev news, AI-digested daily. Never miss a trend at devoured.fyi